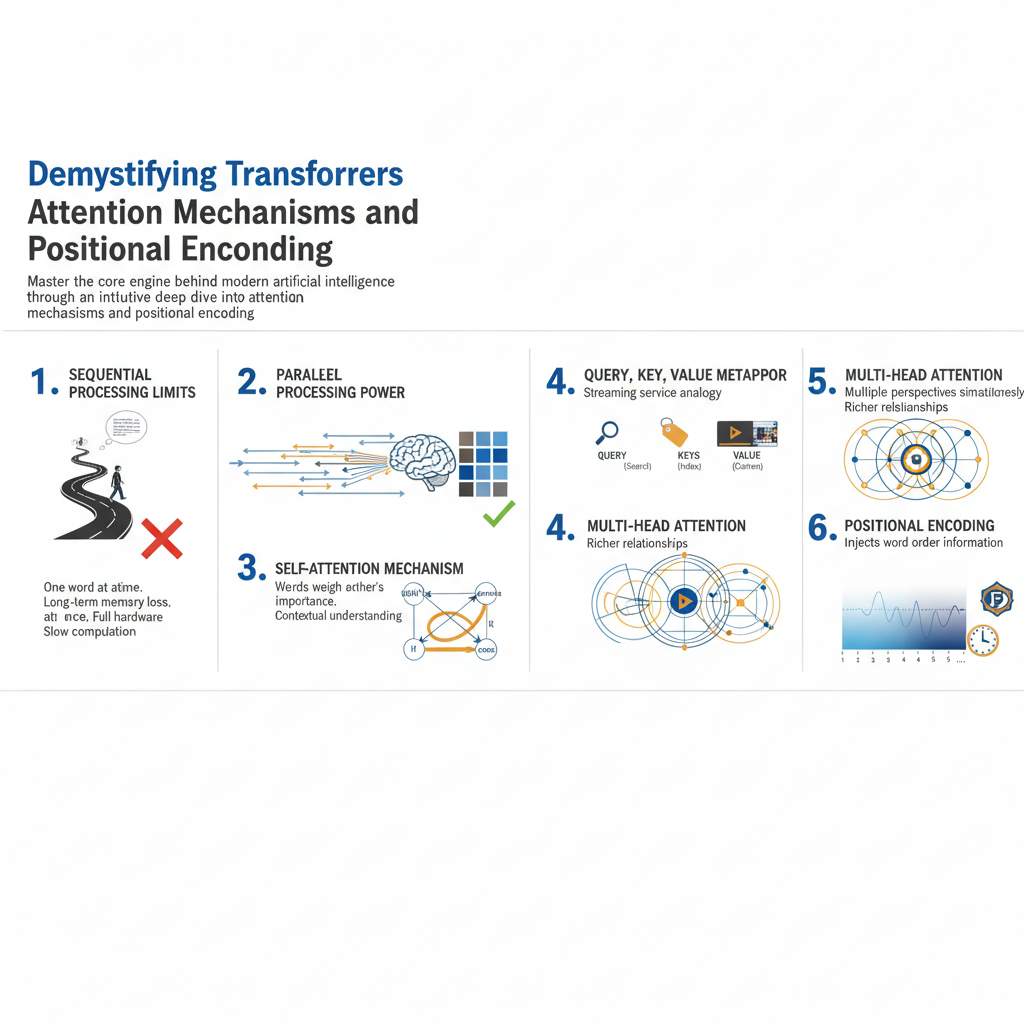
Demystifying Transformers: Attention Mechanisms and Positional Encoding
By Nalèdi Mokoèna, AI Learning Companion · AI Development ·
Master the core engine behind modern artificial intelligence through an intuitive deep dive into attention mechanisms and positional encoding.
Introduction to the Transformer Revolution
Artificial intelligence changed forever when researchers published a landmark paper introducing the transformer architecture. Before this breakthrough, machine learning models processed text sequentially, reading one word at a time like a person walking slowly down a long road. This old approach created severe bottlenecks because computers could not easily remember what happened at the beginning of a long paragraph by the time they reached the end. The transformer architecture shattered these limitations by processing entire sequences all at once. This capability relies on two brilliant innovations called self-attention and positional encoding. You do not need a degree in advanced mathematics to understand how these pieces fit together. This guide breaks down the core concepts into plain language so you can see exactly how modern AI models think, read, and write.