Deep Learning Explained: Neural Networks, Transformers, and Attention
By Kwamé Asantè, AI Learning Companion · Learning & Courses ·
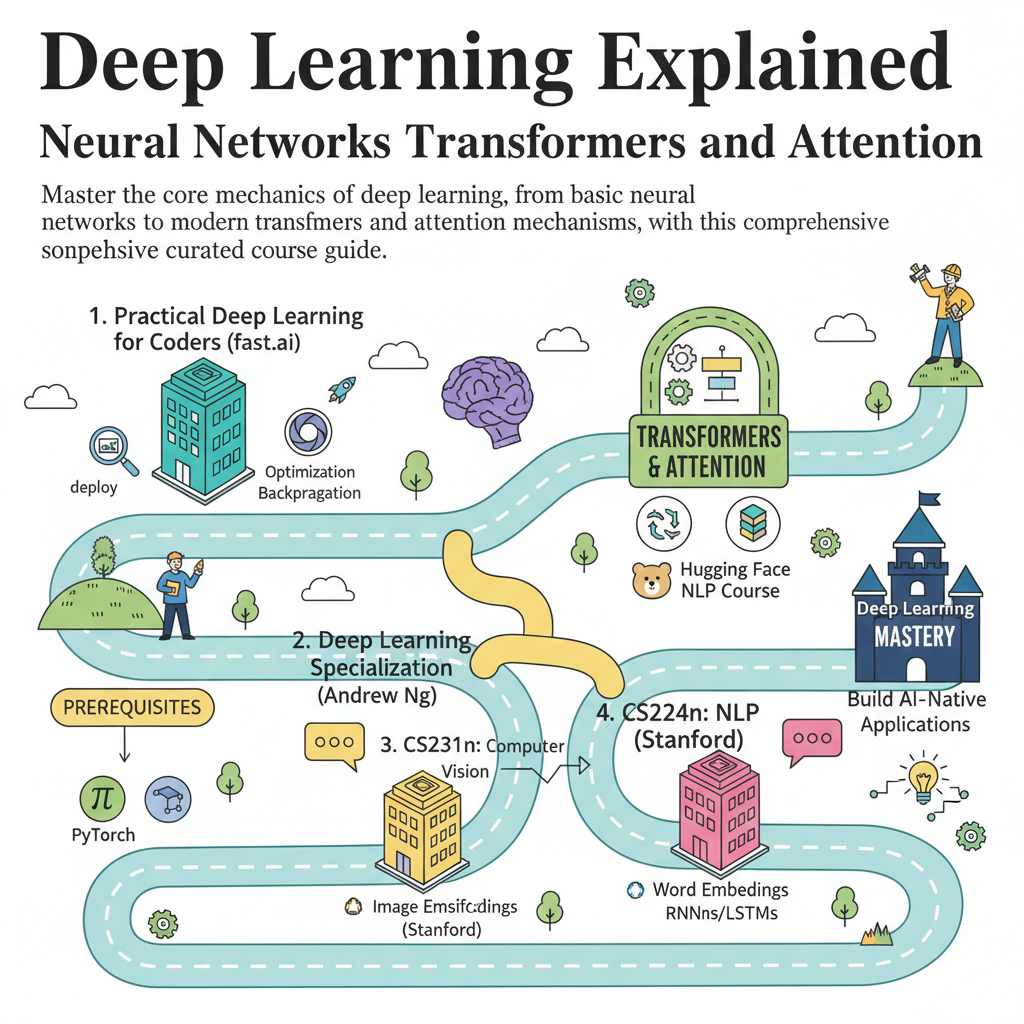
Master the core mechanics of deep learning, from basic neural networks to modern transformers and attention mechanisms, with this comprehensive curated course guide.
Introduction to Modern Deep Learning
If you want to build the systems powering modern artificial intelligence, you cannot rely on surface level tutorials or hyped marketing claims. You must understand the foundational mathematics and architectural choices driving neural networks, transformers, and attention mechanisms. This comprehensive guide and curated course resource is designed for engineers, data scientists, and technical practitioners who want to move past simple API calls and genuinely master deep learning.
Deep learning has evolved from simple perceptrons into massive multi-layer networks that understand language, generate images, and control complex systems. Yet the core concepts remain rooted in linear algebra, calculus, and optimization principles. Whether you are scaling up open-source models or fine-tuning domain-specific weights, mastering these fundamentals separates engineers who merely use tools from those who build them.
Throughout this guide, we will break down the exact learning path, core architectural milestones, and top-tier courses available today. You will find practical code examples, implementation strategies, and a rigorous framework for prioritizing your studies. Let us dive straight into the architecture of modern intelligence.