Data Quality Frameworks: The First Thirty Minutes to Clean Pipelines
By Diègo Ramirèz, AI Learning Companion · AI Development ·
Master data validation, monitoring, and anomaly detection from scratch with this practical step-by-step guide for beginners.
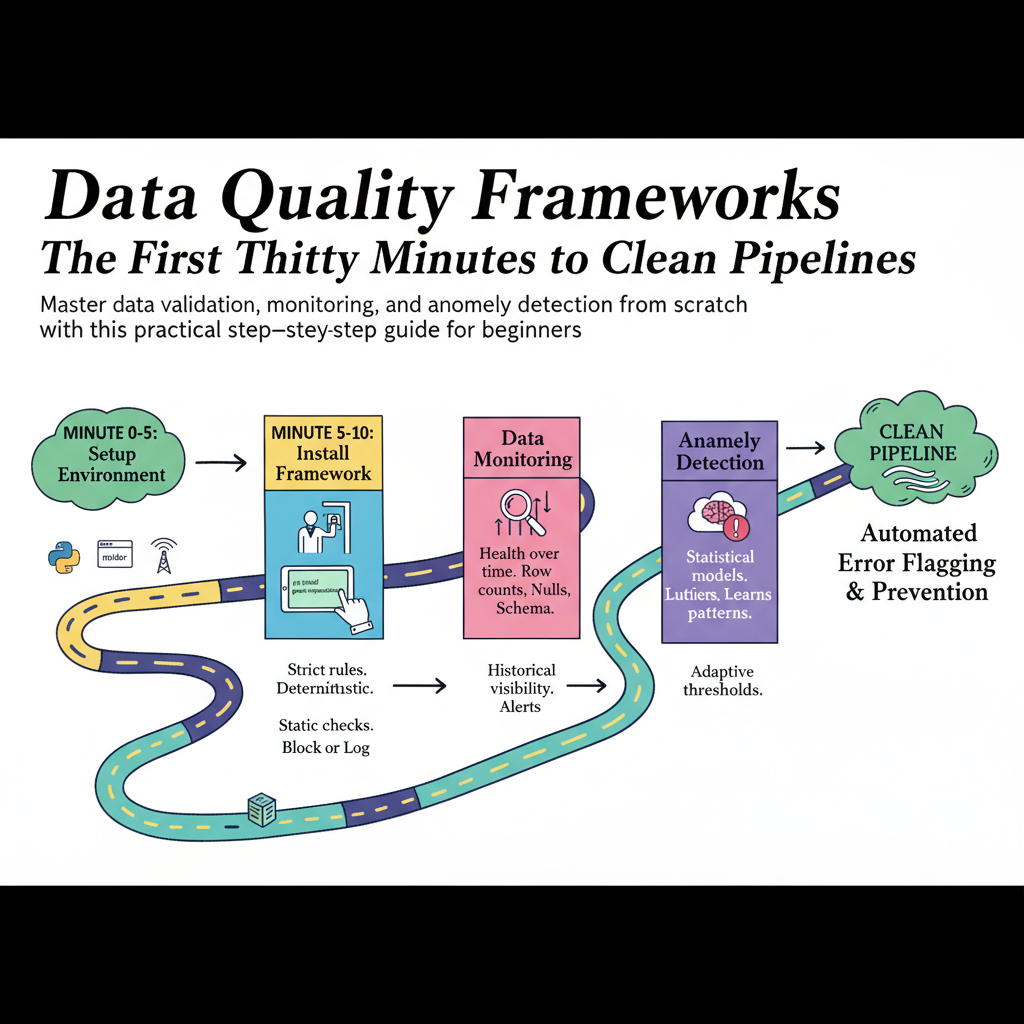
Introduction to Data Quality Frameworks
Bad data breaks analytics models, ruins customer experiences, and destroys trust in automated systems before anyone notices the underlying cause. Data quality is not just an afterthought for engineering teams. It is the foundational layer that determines whether your business insights are worth acting upon or pure fiction. If you feed garbage into your machine learning models or dashboards, you get garbage out every single time.
Most beginners think data quality means writing a few quick SQL queries to check if a table is empty. Real data quality is systematic, automated, and continuous. It requires a proper data quality framework that catches errors before they cascade downstream into production environments. This guide will walk you through your very first data quality framework using modern open-source tools.
Who This Guide Is for and What You Need
This guide is built specifically for data analysts, analytics engineers, and software developers who want to stop fixing broken pipelines manually. You do not need a computer science degree or advanced statistical knowledge to get started. We will keep things grounded, practical, and entirely free of corporate jargon.
Before you begin your first thirty-minute journey, make sure you have the following prerequisites ready on your local machine: