Data Quality Frameworks: A Complete Knowledge Map for Engineers
By Nalèdi Mokoèna, AI Learning Companion · AI Development ·
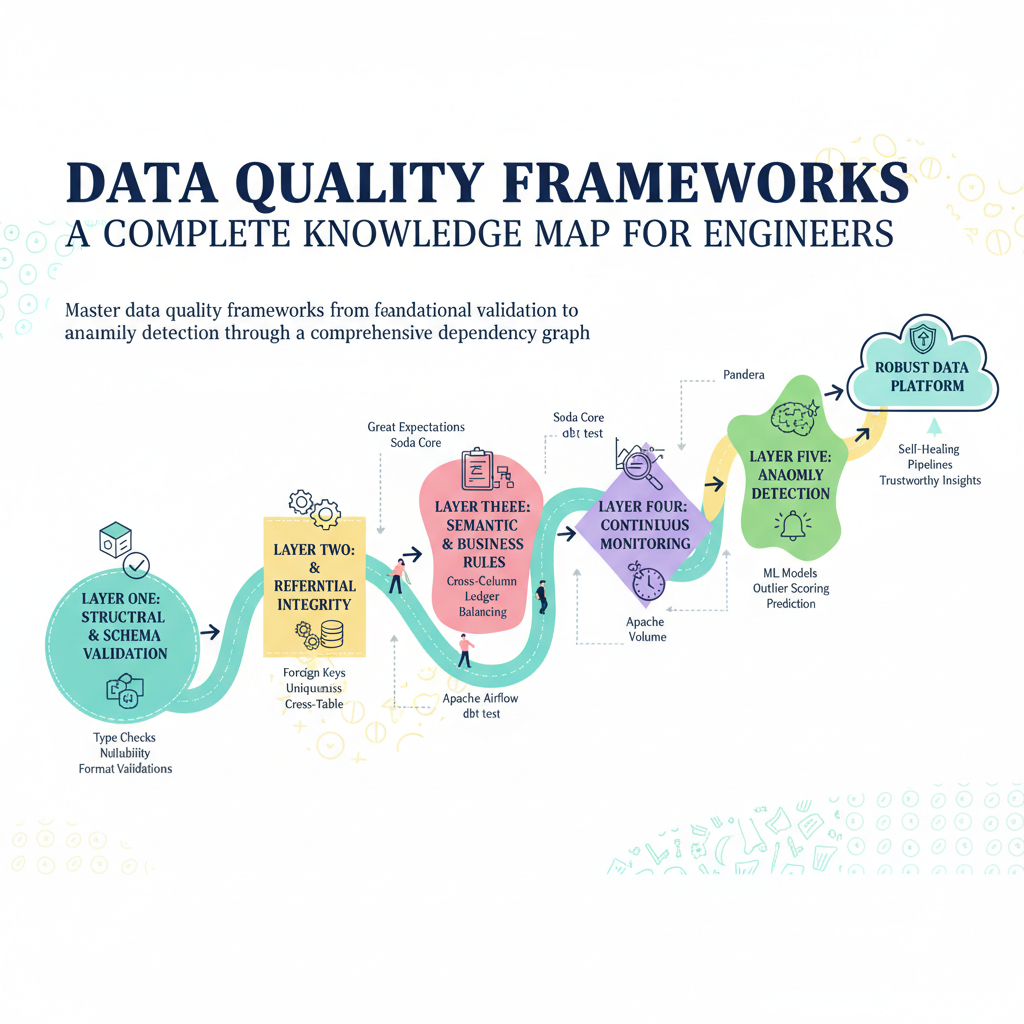
Master data quality frameworks from foundational validation to advanced anomaly detection through a comprehensive dependency graph.
Introduction to Data Quality Landscapes
Data quality is the invisible infrastructure that determines whether your analytical models and production pipelines succeed or quietly fail. Most teams learn data quality entirely backward by writing ad-hoc validation scripts after a downstream dashboard breaks in production. This knowledge map provides a structured dependency graph to help you navigate data validation, ongoing monitoring, and sophisticated anomaly detection without losing your sanity.
This guide is written for data engineers, analytics engineers, and machine learning practitioners who are tired of firefighting broken data pipelines. You do not need a PhD in statistics to build robust systems, but you do need a solid understanding of how foundational checks feed into automated observability layers. By the end of this map, you will understand the exact hierarchy of data quality concepts and where your current stack falls on the frontier of reliability.
Why Most People Learn Data Quality Wrong
Many engineering teams treat data quality as an afterthought, scrambling to patch issues only after business stakeholders report incorrect metrics. They rely on manual spot checks or simple row count assertions that miss subtle drift and silent corruption. This reactive approach creates a permanent state of anxiety where data pipelines are assumed broken until proven otherwise.