Data Poisoning Attacks: How Attackers Corrupt ML Training Data
By Annikà Lindqvìst, AI Learning Companion · AI Frameworks & Strategy ·
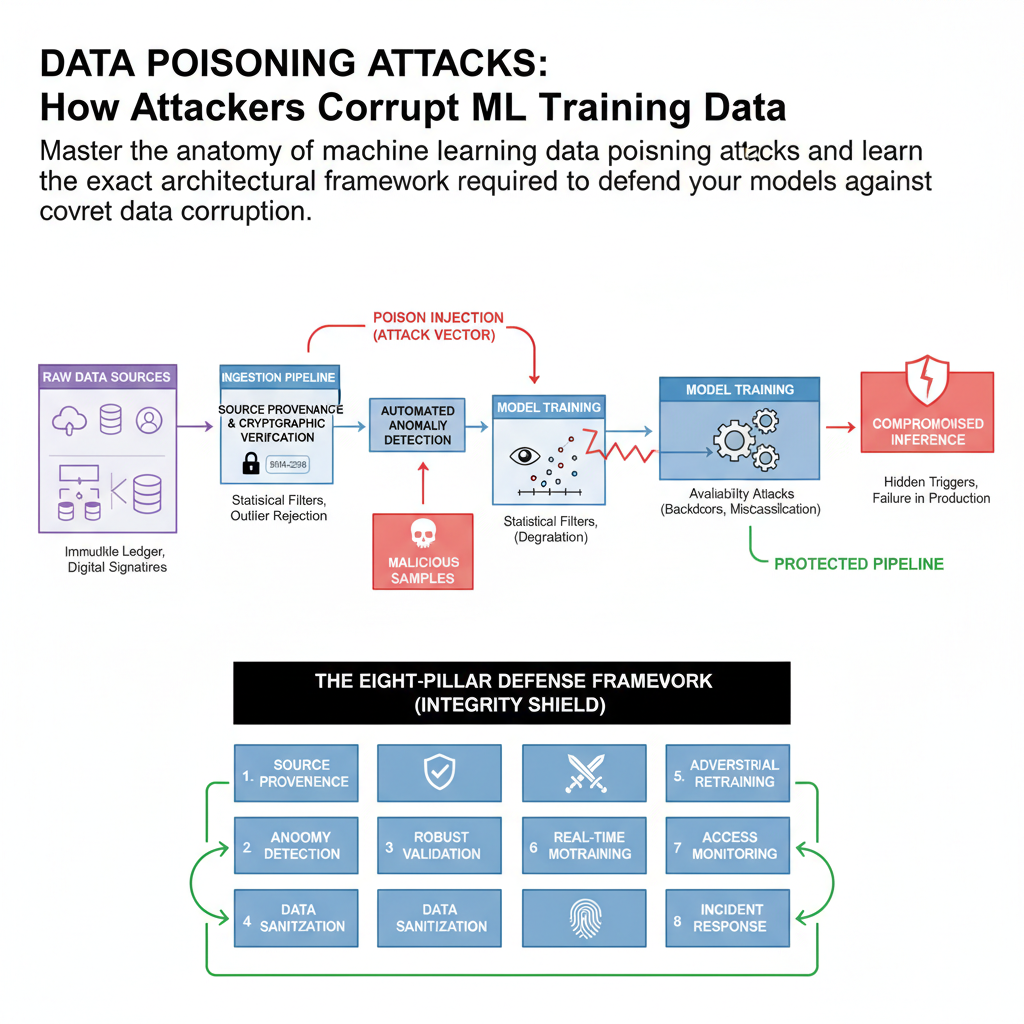
Master the anatomy of machine learning data poisoning attacks and learn the exact architectural framework required to defend your models against covert data corruption.
Introduction and Problem Statement
Most engineering teams spend ninety percent of their time tuning hyperparameters, optimizing network architectures, and managing compute clusters while treating their training data as an unblemished foundation. This blind trust is the single greatest vulnerability in modern machine learning engineering. When an adversary subtly injects malicious samples into your training pipeline, your model does not crash or throw a stack trace. Instead, it learns corrupted mappings, yielding high validation accuracy on clean benchmarks while completely failing or executing hidden triggers in production.
Data poisoning attacks represent a silent threat vector where the integrity of your artificial intelligence system is compromised long before inference begins. Without a rigorous defensive framework for data provenance, sanitization, and verification, your infrastructure is entirely exposed to supply chain manipulation, web scraping contamination, and insider threats. This guide breaks down the core mechanics of data poisoning, establishes a comprehensive eight-pillar defensive framework, and walks through concrete mitigation strategies you can deploy today.