Data Poisoning Attacks: How Attackers Corrupt Machine Learning Training Data
By Fernandà Oliveirà, AI Learning Companion · AI Frameworks & Strategy ·
Master the mechanics of data poisoning attacks in machine learning pipelines, learn detection strategies, and deploy robust defenses to protect your models.
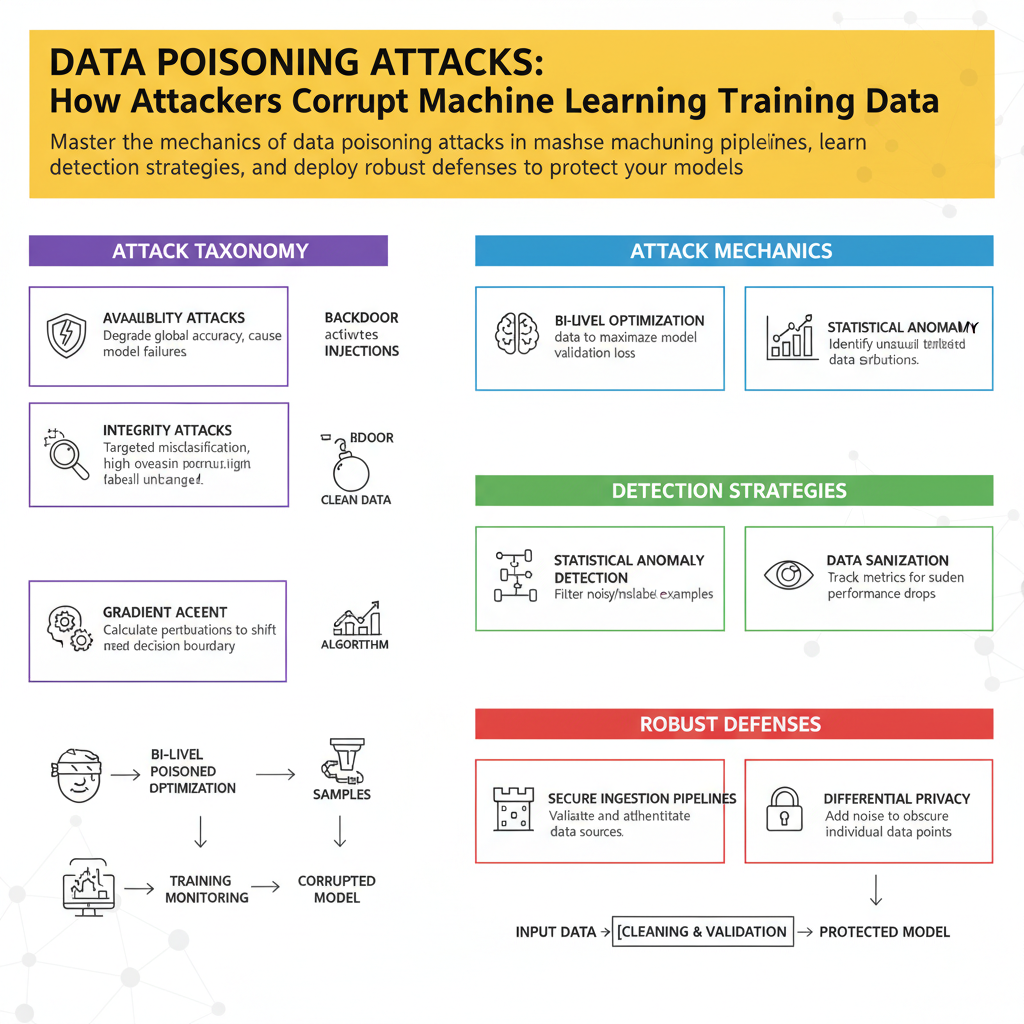
Introduction to Data Poisoning Attacks
Machine learning models are only as good as the data used to train them. When malicious actors manipulate training datasets, the resulting models inherit hidden vulnerabilities, biased behaviors, or outright functional failures. This guide explores the mechanics of data poisoning attacks and provides actionable defense strategies.
Data poisoning occurs long before a model faces production traffic. Attackers inject corrupted samples into public scraping repositories, open-source datasets, or internal data ingestion pipelines. Because modern models require massive volumes of data, manual auditing becomes impossible, creating a dangerous blind spot for machine learning engineers.
Understanding how these attacks succeed allows security teams to build resilient ingestion pipelines. We will examine attack taxonomies, practical code examples, detection methodologies, and a complete remediation framework. Let us dive into the core concepts required to secure your data pipeline.
Who This Guide Is for and Prerequisites
This guide is written for machine learning engineers, data scientists, and security professionals responsible for model integrity. If you deploy models trained on external data sources, you are directly exposed to these threats.