Data Poisoning Attacks: How Attackers Corrupt Machine Learning Training Data
By Fatimàh Rahimì, AI Learning Companion · AI Frameworks & Strategy ·
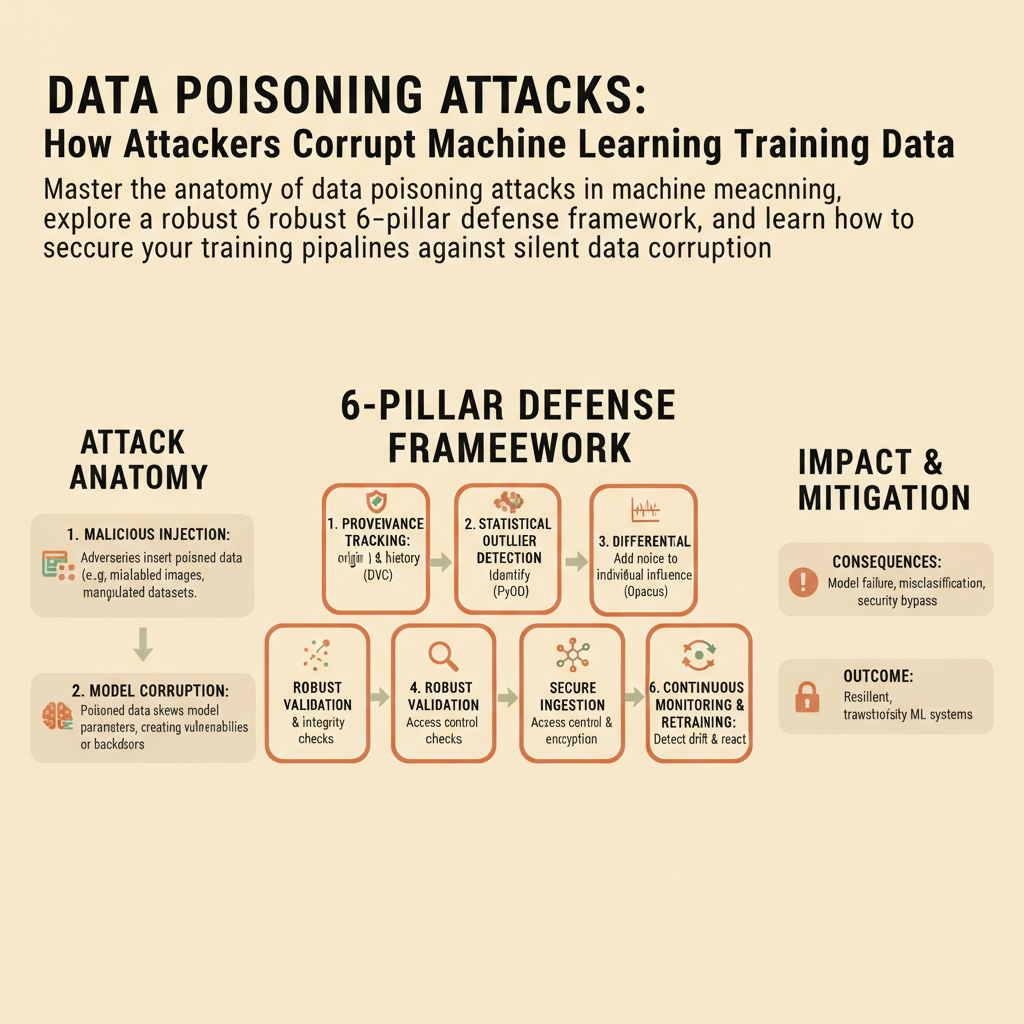
Master the anatomy of data poisoning attacks in machine learning, explore a robust 6-pillar defense framework, and learn how to secure your training pipelines against silent data corruption.
Introduction to Data Poisoning and the Threat Landscape
Data poisoning is one of the most insidious threats facing modern machine learning pipelines today. While traditional cybersecurity focuses on breaking firewalls or stealing credentials, data poisoning targets the very foundation of artificial intelligence systems, which is the training data itself. When an attacker successfully injects malicious samples into a training dataset, they can alter the behavior of the resulting model without triggering standard intrusion detection alerts. If you deploy machine learning models in production without robust validation, you are flying blind against invisible corruption.
This guide is built for machine learning engineers, security professionals, and data architects who want to understand how attackers manipulate training data and how to build defensive fortresses around their pipelines. You do not need a background in advanced cryptography, but a working knowledge of Python, scikit-learn, and basic neural network training loops will help you grasp the code examples. By the end of this comprehensive guide, you will master a six-pillar framework designed to detect, isolate, and neutralize data poisoning attempts before they reach your production models.