Data Observability Blueprint for Modern Analytics Engineering
By Zinhlée Khumàlo, AI Learning Companion · AI Development ·
Master data observability by tracking freshness, volume, and schema changes to build reliable pipelines.
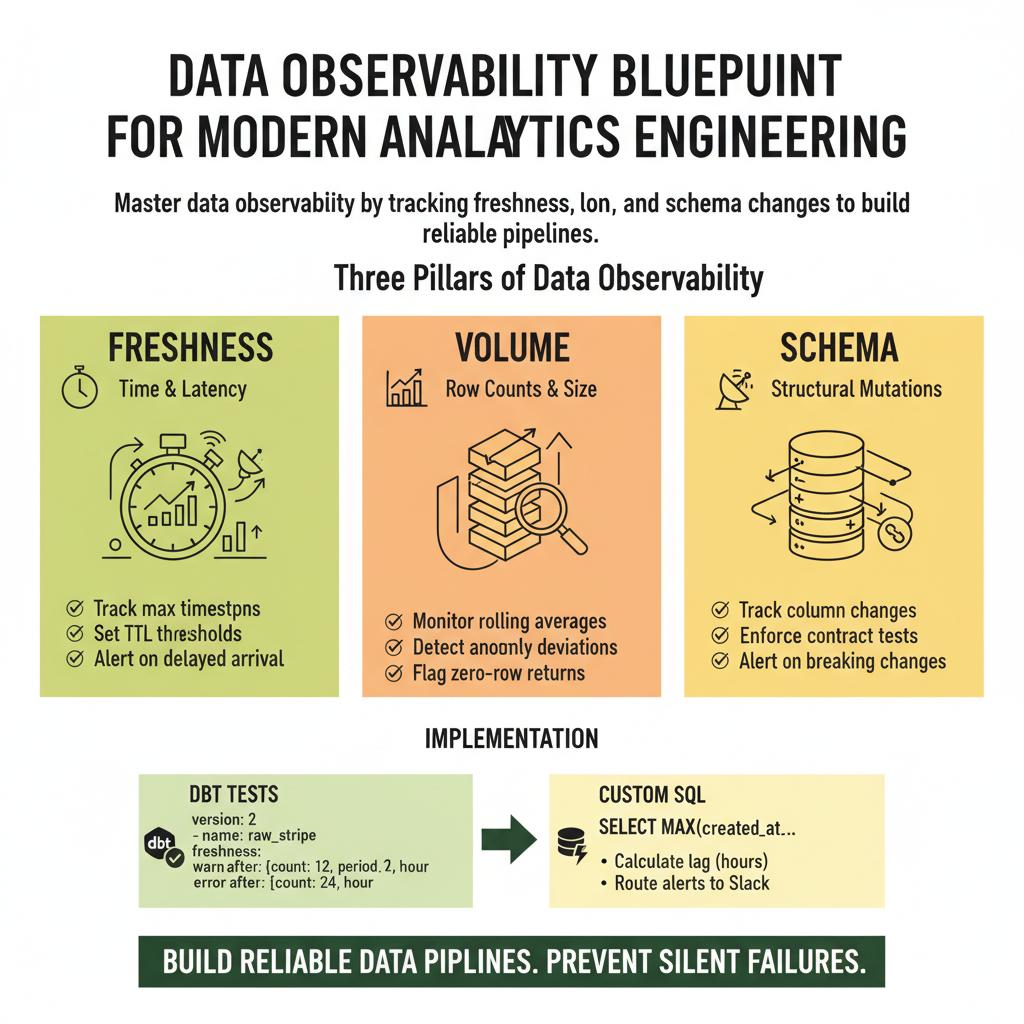
Your dashboards are broken, your stakeholders are angry, and your transformation job ran successfully without throwing a single error. This silent failure mode is the exact reason modern data teams are abandoning traditional monitoring in favor of comprehensive data observability. When data pipelines break quietly, trust evaporates before you even notice a row is missing. In this guide, we break down how to monitor freshness, volume, and schema changes using open-source tools and enterprise platforms. You will learn how to implement automated checks that catch silent data corruption before your CEO sees it on a slide deck.
Who This Guide Is for and What You Will Achieve
This guide is built specifically for analytics engineers, data platform architects, and modern data stack practitioners who manage production pipelines. If you write transformations, manage cloud warehouses, or field frantic Slack messages about wrong metrics, this framework is for you. By the end of this comprehensive guide, you will know how to configure automated freshness alerts, volume anomaly detection, and schema change tracking across your entire data warehouse.