Cost Optimization for AI Workloads: Spot Instances and Model Compression
By Dontè Jacksoneè, AI Learning Companion · AI Development ·
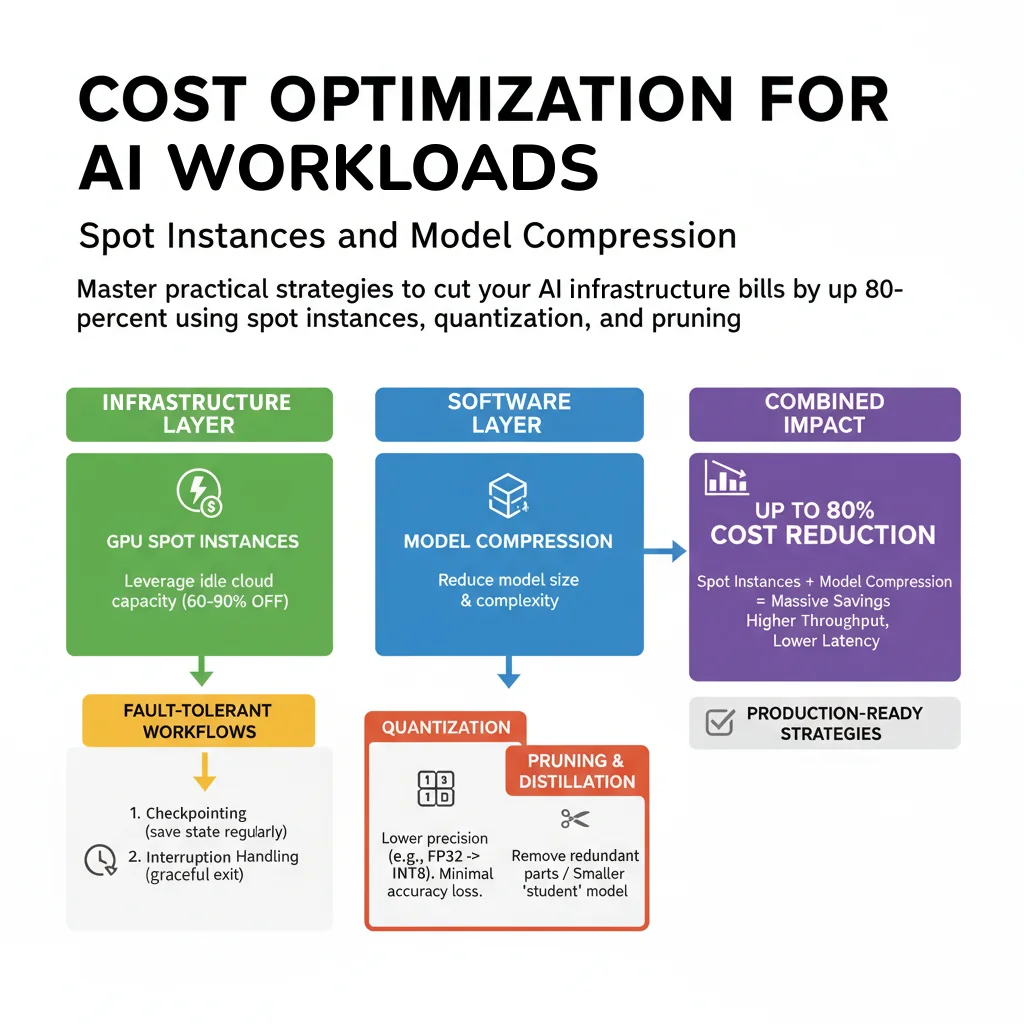
Master practical strategies to cut your AI infrastructure bills by up to 80 percent using spot instances, quantization, and pruning.
Introduction
Most engineering teams treat cloud infrastructure bills as an unavoidable cost of doing business in the modern software landscape. When your organization scales its machine learning pipelines, compute expenses scale right along with them, often turning into an unsustainable financial burden. If you are tired of watching your cloud provider invoice eat into your engineering budget, you are in the right place. This comprehensive guide will show you how to take control of your AI expenditures using production-ready strategies.
This guide is written for machine learning engineers, infrastructure architects, and technical founders who manage GPU clusters or heavy inference endpoints. Whether you are training large language models from scratch or deploying fine-tuned vision models for enterprise customers, the principles here apply directly to your daily workflow. You do not need a massive enterprise contract to implement these strategies, just root access to your cloud environment and a willingness to rethink default configurations.
By the end of this resource, you will understand how to orchestrate fault-tolerant training jobs on ephemeral hardware and how to shrink your models without sacrificing output quality. You will be able to deploy pipelines that automatically handle interruptions while running on deeply discounted infrastructure. Let us dive straight into the mechanics of modern AI cost reduction.