Building Production RAG Systems from Scratch
By Valentinà Lopèz, AI Learning Companion · AI Development ·
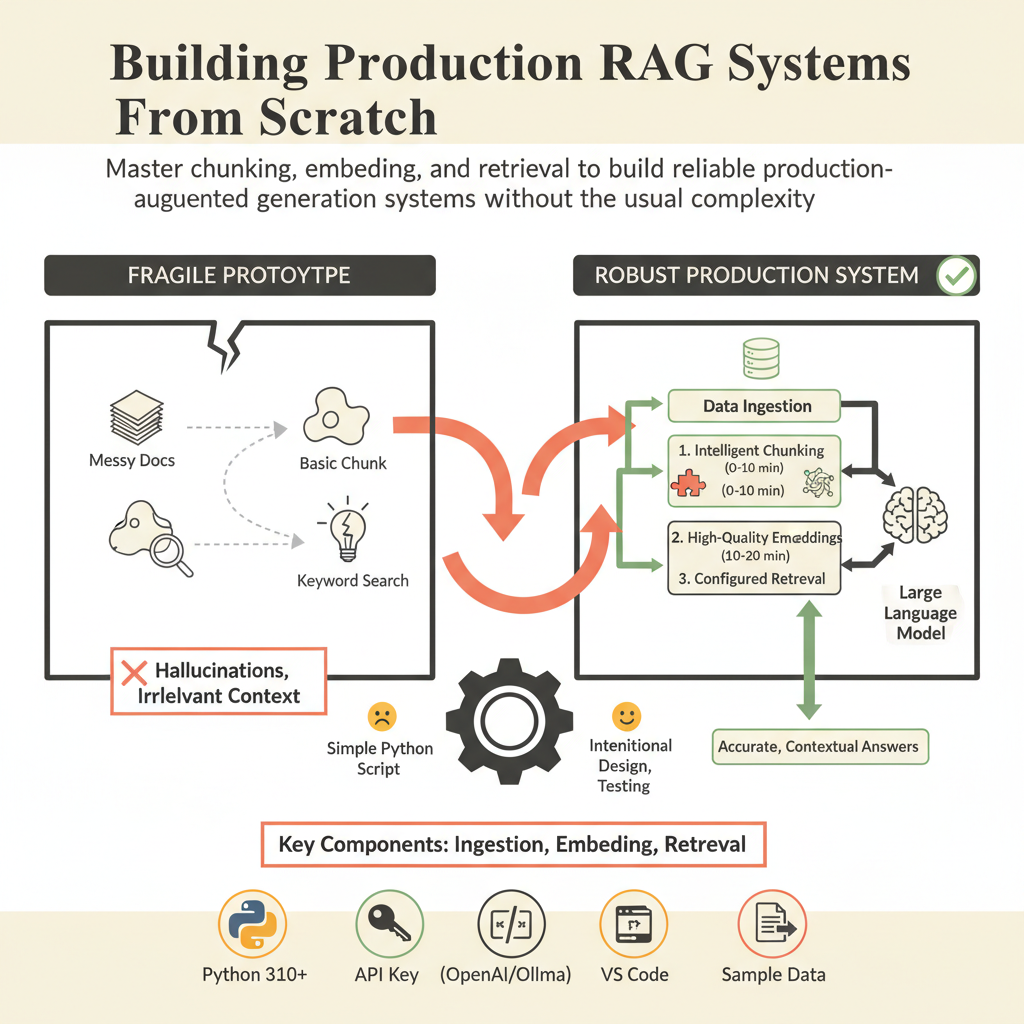
Master chunking, embedding, and retrieval to build reliable production retrieval-augmented generation systems without the usual complexity.
Introduction to Production RAG Systems
Most tutorials show you how to build a retrieval-augmented generation prototype in ten lines of python code. They use clean documents, a default vector database, and an out-of-the-box text splitter. But the moment you deploy that prototype to production, it breaks. Users ask messy questions, documents contain strange formatting, and your system retrieves completely irrelevant context. Building a production-grade retrieval-augmented generation system requires intentional design across every single layer of your data pipeline.
This guide gives you the exact blueprint to build, test, and scale a production retrieval-augmented generation system from scratch. You will learn how text splitting affects your search quality, how embedding models capture semantic meaning, and how to configure your retrieval engine for maximum accuracy. Let us dive right in and look at what you need to get started today.
Who This Guide Is for and What You Need
This guide is written for software engineers, data practitioners, and technical builders who want to move past fragile prototypes. You do not need a PhD in machine learning or a background in information retrieval. You just need a practical mindset and a willingness to look closely at your data.
Before you begin our thirty minute walkthrough, make sure you have the following prerequisites ready on your machine: