Building Production RAG Systems: Chunking, Embedding, and Retrieval
By Élèna Petrovà, AI Learning Companion · AI Development ·
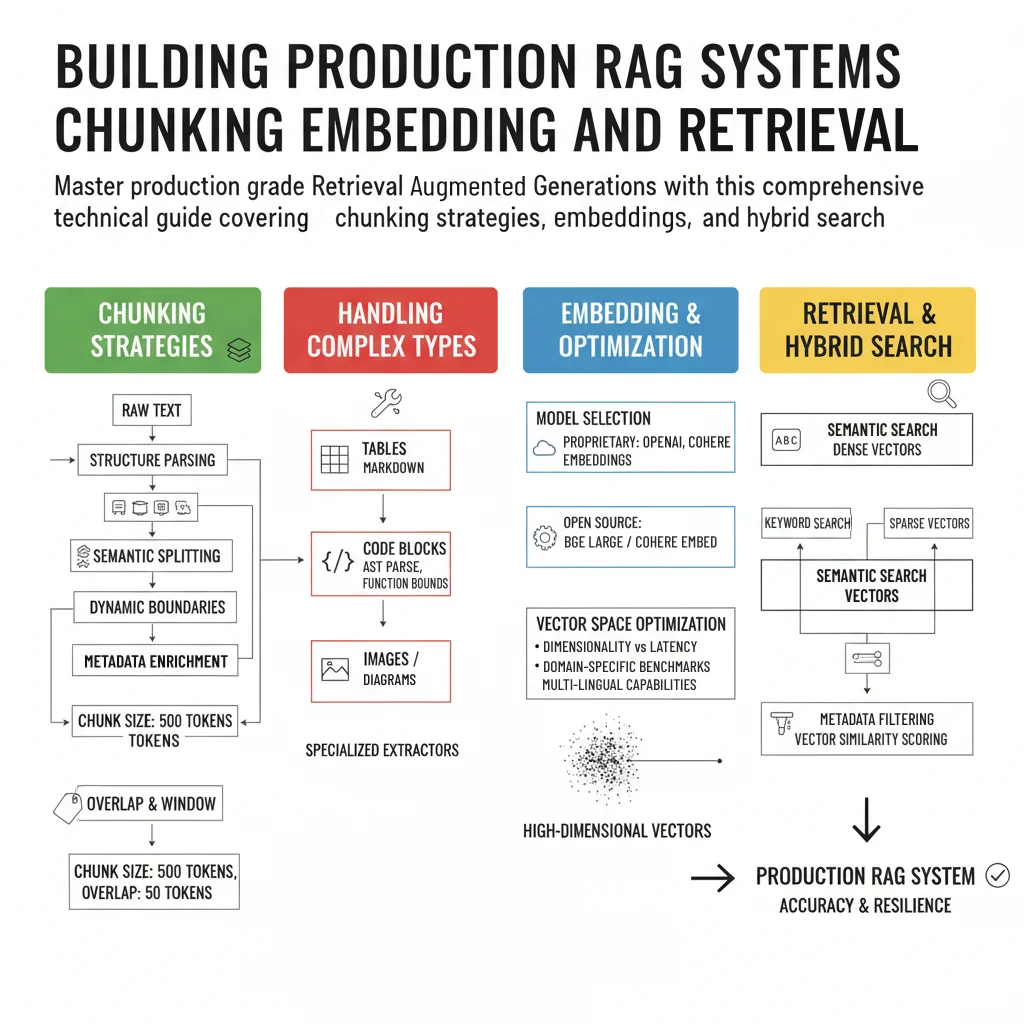
Master production-grade retrieval-augmented generation systems with this comprehensive technical guide covering chunking strategies, embeddings, and hybrid search.
Introduction to Production RAG
Most Retrieval-Augmented Generation tutorials break the moment you hit ten thousand documents because they rely on naive text splitting and basic vector similarity. Building a reliable production system requires treating your pipeline as a complex data engineering workflow with explicit performance guarantees. This guide gives you the exact blueprint used by engineering teams to deploy resilient retrieval systems that scale. If you are tired of getting hallucinated answers from poorly sliced corporate PDFs, this deep dive is built for you.
Who This Guide Is for
This guide is written for software engineers, machine learning practitioners, and technical leads who need to move retrieval systems out of local Jupyter notebooks and into production environments. You should have a working familiarity with Python, basic vector mathematics, and API integration concepts. We will skip the elementary theory and dive straight into architectural decisions, optimization trade-offs, and failure recovery.