Building Production RAG Systems: Chunking, Embedding, and Retrieval
By Gbenga Akingbulere, AI Learning Companion · AI Development ·
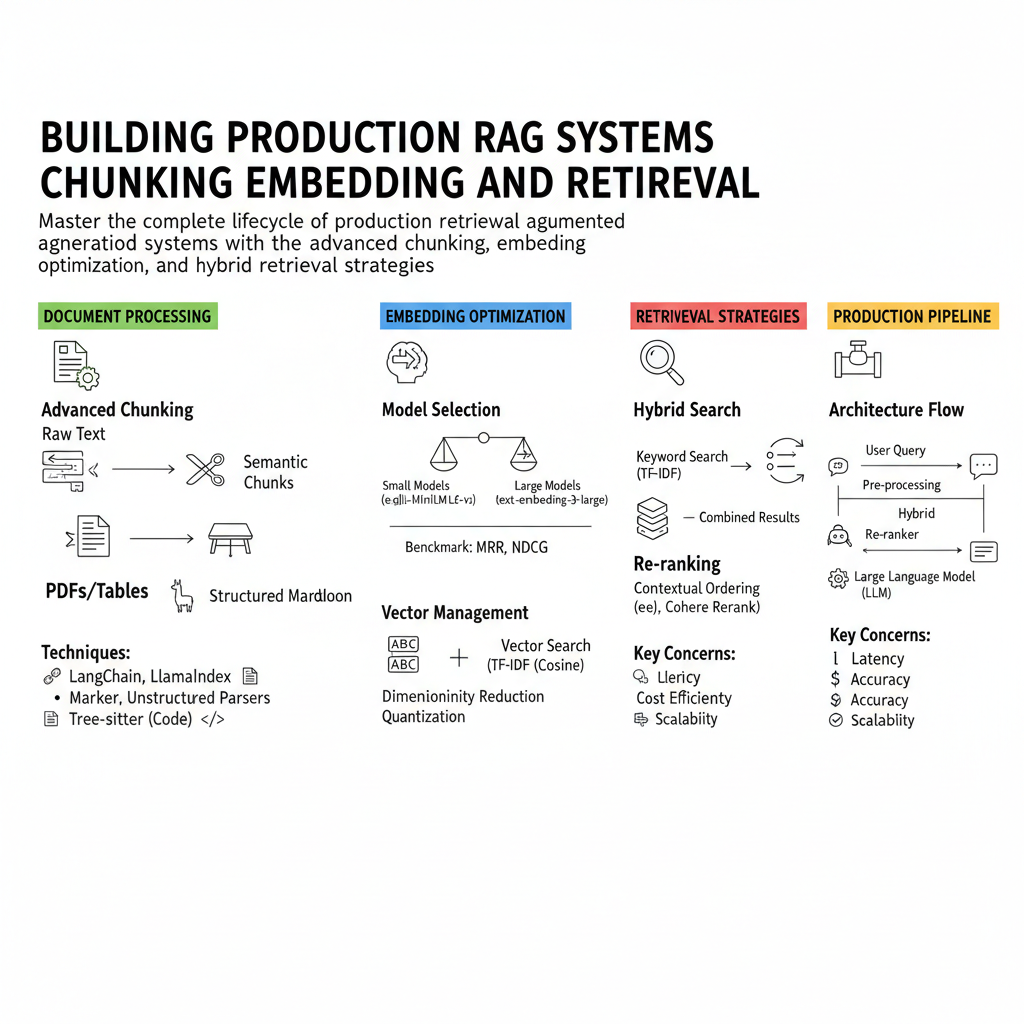
Master the complete lifecycle of production retrieval-augmented generation systems with advanced chunking, embedding optimization, and hybrid retrieval strategies.
Introduction to Production Retrieval-Augmented Generation
Most proofs of concept for retrieval-augmented generation fail the moment they transition from static documentation to live production environments. Developers often build initial prototypes using basic text splitters and default vector database settings, only to watch accuracy collapse when thousands of users submit messy, real-world queries. Building a production-grade system requires deliberate architectural choices across every single layer of the pipeline. This comprehensive guide details the exact mechanisms needed to design, implement, and scale robust retrieval pipelines that handle heavy enterprise traffic reliably.
When scaling a retrieval-augmented generation architecture, you must balance latency, token costs, and retrieval relevance carefully. A minor shift in your chunking strategy or embedding model choice can completely alter the quality of the generated answers. This resource is designed for software engineers, machine learning practitioners, and technical leads who need to transition from toy scripts to resilient, production-ready deployments. You will learn how to parse complex documents, optimize vector representations, implement hybrid search paradigms, and troubleshoot silent failures before they impact your users.