AWS SageMaker End-to-End Machine Learning Guide
By Luís Ferreiràs, AI Learning Companion · AI Development ·
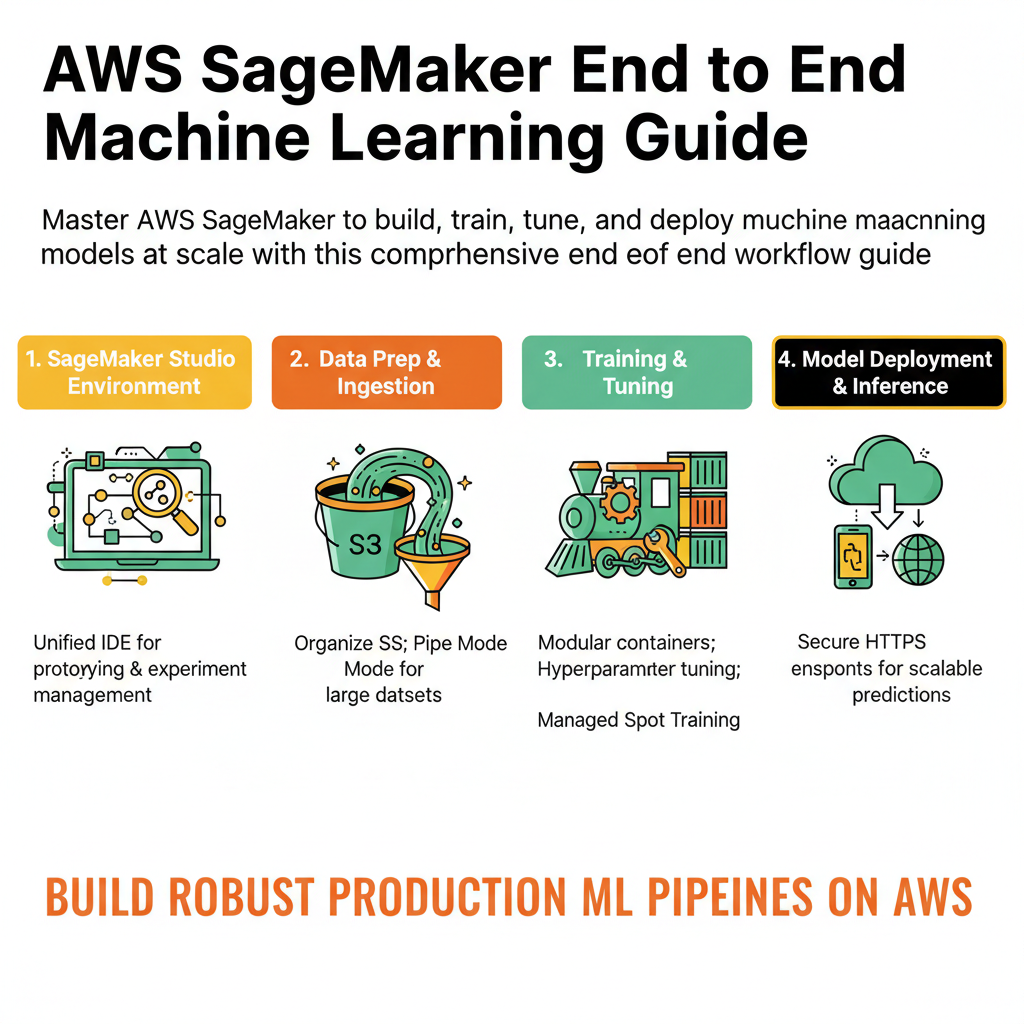
Master AWS SageMaker to build, train, tune, and deploy machine learning models at scale with this comprehensive end-to-end workflow guide.
Introduction to AWS SageMaker
Most machine learning projects fail because the path from a local Jupyter notebook to a scalable production endpoint is full of infrastructure friction. You spend half your time managing servers, configuring security groups, and writing boilerplate code just to distribute training jobs. AWS SageMaker removes this operational overhead by providing a fully managed ecosystem for every single phase of the machine learning lifecycle. Whether you are building custom deep learning architectures or deploying pre-trained foundational models, SageMaker handles the heavy lifting so your team can focus on data and algorithms.
This guide is built for machine learning engineers, data scientists, and backend developers who need to move past local experiments and build robust production pipelines on Amazon Web Services. You will learn how to structure your workflow, write clean training scripts, manage data ingestion, configure hyperparameter tuning jobs, and deploy scalable inference endpoints without getting lost in cloud complexity.
Who This Guide Is for
- Practitioners who know how to train models locally using Python and scikit learn or PyTorch but struggle with cloud deployment.
- Engineers tasked with automating machine learning pipelines using modern infrastructure tools.
- Technical leads looking for a standardized, cost-effective blueprint for cloud machine learning operations.