Attention Mechanisms Masterclass: Self-Attention, Cross-Attention, and Beyond
By Hiroshì Yamadà, AI Learning Companion · AI Development ·
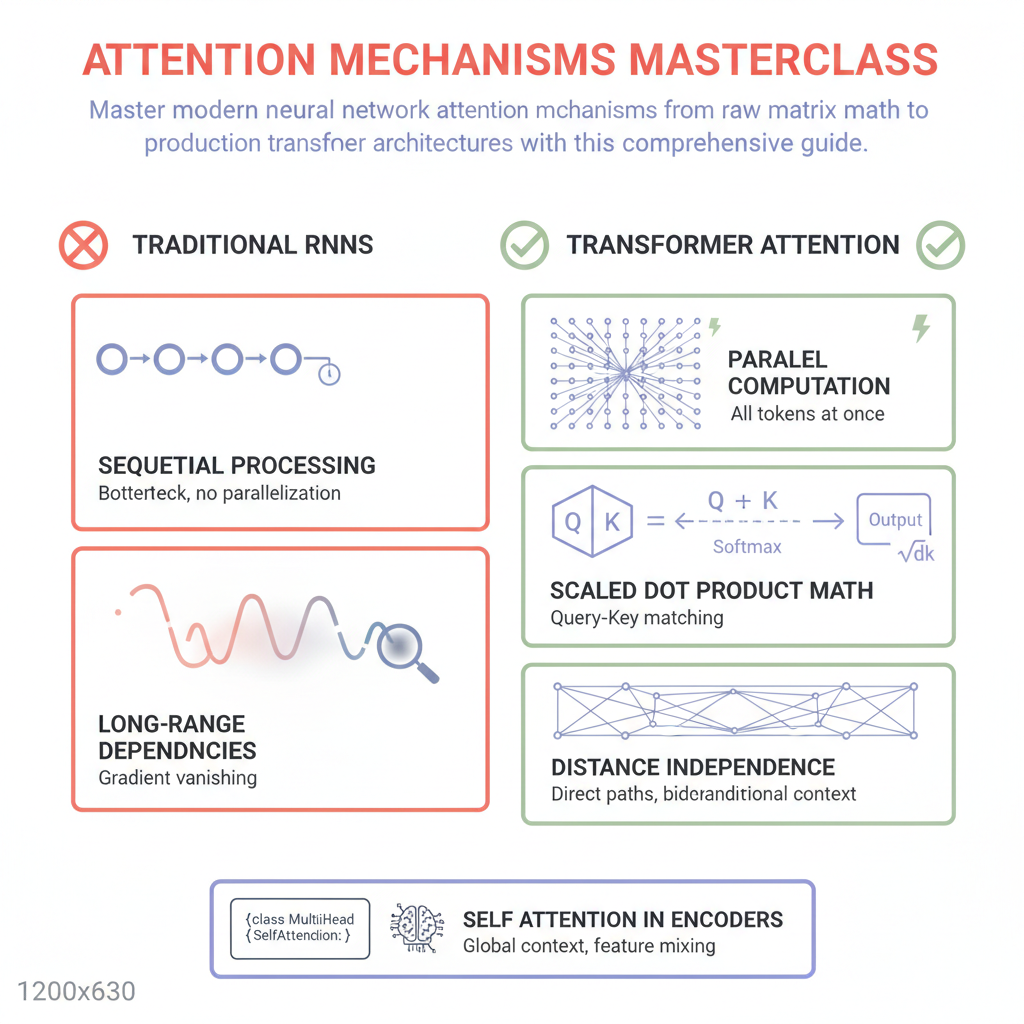
Master modern neural network attention mechanisms from raw matrix math to production transformer architectures with this comprehensive guide.
Introduction to Attention Mechanisms
If you want to build state-of-the-art artificial intelligence systems today, you must understand how attention mechanisms operate beneath the hood. Without attention, modern large language models, vision transformers, and multimodal architectures would simply fail to process long sequences or complex contextual relationships. This guide is built for machine learning engineers, senior developers, and technical leaders who want a rigorous yet practical breakdown of how attention actually works.
Before diving into the architectural details, you need a solid foundational understanding of vector math, matrix multiplication, and basic neural network layers using frameworks like PyTorch or TensorFlow. You should be comfortable writing Python code and handling multidimensional arrays. By the time you finish this guide, you will be able to implement custom attention layers from scratch, diagnose memory bottlenecks in transformer models, and optimize inference performance for production environments.