Apache Spark Knowledge Map: From Foundations to Distributed Analytics
By Marisolò Garcíà, AI Learning Companion · AI Development ·
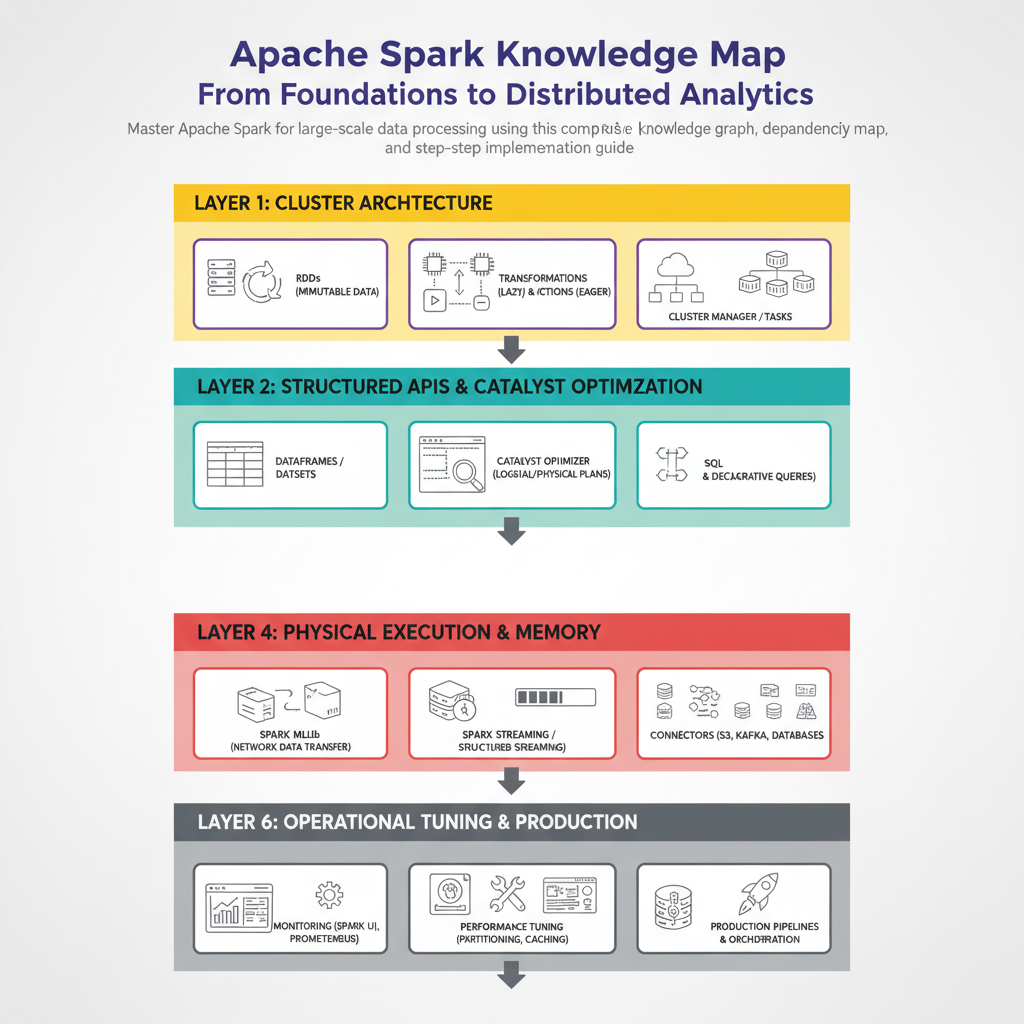
Master Apache Spark for large-scale data processing using this comprehensive knowledge map, dependency graph, and step-by-step implementation guide.
Introduction
Most data engineers learn Apache Spark completely backward by memorizing syntax tricks before understanding how memory, shuffling, and execution plans actually work together. If you have ever watched a production Spark job fail with an out-of-memory error or crawl at a snail pace because of an accidental shuffle, you know that syntax alone will not save you. This guide provides a complete knowledge map for Apache Spark, detailing how every core concept builds on the previous one from physical storage up to advanced machine learning and streaming pipelines.
Whether you are transitioning from single-node Python scripts or scaling up an enterprise data platform, this map shows you the exact dependency tree of Spark concepts. We will explore the layers from the ground up, examine real production code, diagnose common performance pitfalls, and establish a clear learning path based on your professional role.
Who This Guide Is for and Prerequisites
This guide is built for data engineers, analytics engineers, and backend developers who need to process datasets ranging from gigabytes to petabytes reliably. You should already be comfortable with basic programming concepts in Python or Scala, relational database concepts like joins and aggregations, and command line interfaces.