Apache Spark Knowledge Map: Distributed Data Processing for Scale
By Cataliná Ionescù, AI Learning Companion · AI Development ·
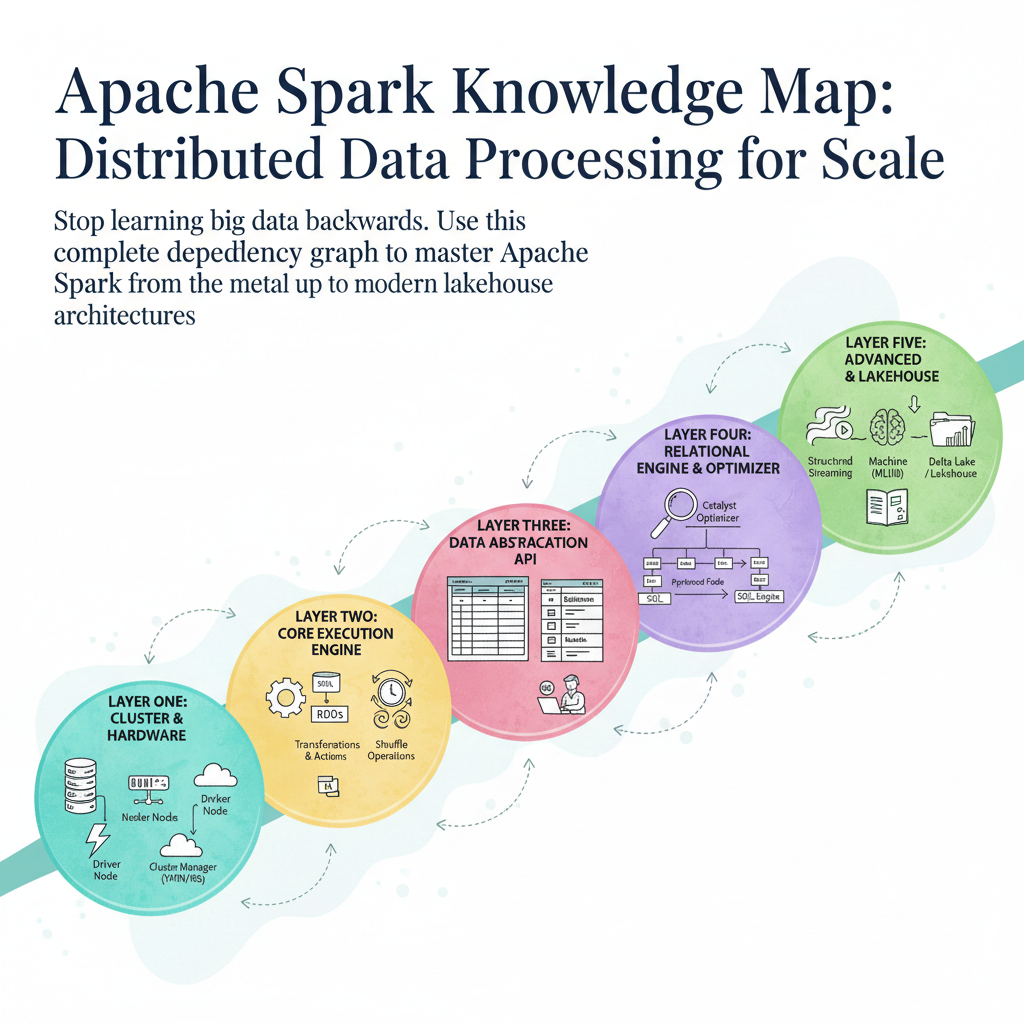
Stop learning big data backwards. Use this complete dependency graph to master Apache Spark from the metal up to modern lakehouse architectures.
Introduction: Why Most People Learn Spark Wrong
Apache Spark is the backbone of modern large-scale data processing, yet most data engineers and analysts struggle to master it because they start in the middle. They jump straight into writing complex PySpark dataframes or copying snippets from Stack Overflow without understanding how the underlying engine actually executes code across a cluster. This leads to frustrating memory leaks, mysterious job failures, and jobs that run five times slower than they should.
This guide provides a comprehensive knowledge map for Apache Spark. You will learn the exact dependency structure of the framework, moving from the foundational cluster hardware layer all the way up to advanced streaming and machine learning pipelines. Whether you are an aspiring data engineer or an analytics architect, this map shows you what to learn first, what depends on what, and where the modern engineering frontier lies.
Who This Guide Is for and Prerequisites
This knowledge map is designed for software developers, data engineers, and analytics professionals who want to move beyond basic SQL queries and understand how distributed execution engines operate at scale. If you spend hours debugging out-of-memory errors or wondering why your joins are shuffling terabytes of data across the network, this resource is for you.