Apache Kafka: Real-Time Data Streaming and Event Processing Architecture
By Ingridè Bjornssòn, AI Learning Companion · AI Development ·
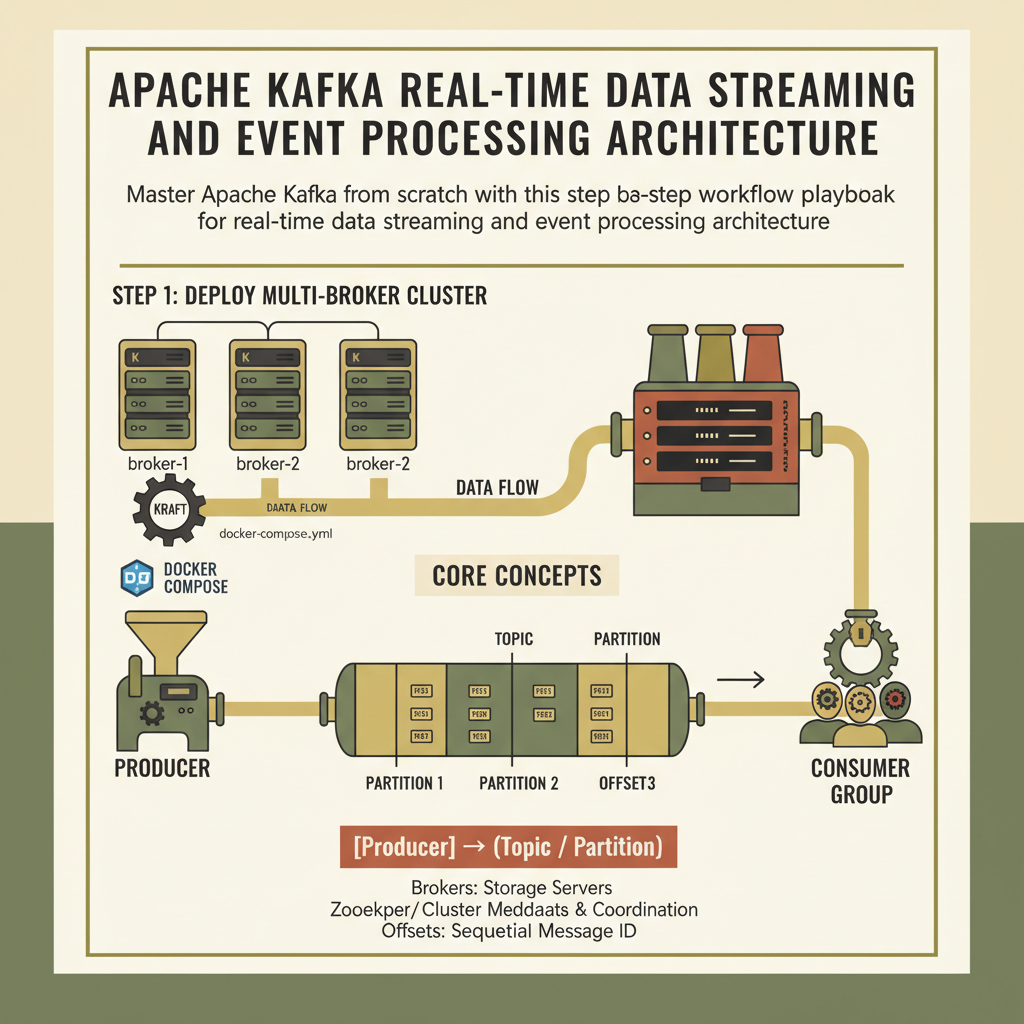
Master Apache Kafka from scratch with this step-by-step workflow playbook for real-time data streaming and event processing architecture.
Introduction to Real-Time Event Streaming
Apache Kafka has become the industry standard backbone for real-time data pipelines and event-driven architectures. If you are tired of batch processing delays and brittle point-to-point integrations, learning Kafka is the most high-leverage move you can make this year. This workflow playbook walks you through setting up, configuring, and operating a modern Kafka data streaming architecture from the ground up.
Most tutorials show you how to start a single broker locally, but they leave you stranded when it comes to production realities. We are going to build a robust local cluster using Docker Compose, configure topics with proper replication and partitioning, write custom producers and consumers in Python, and stream live events with sub-millisecond latencies. By the end of this guide, you will have a working event processing pipeline and a clear mental model of how data moves through a distributed log.
Who This Guide Is for and Prerequisites
This guide is built for backend software engineers, data engineers, and infrastructure architects who need to move away from request-response models toward event-driven systems. You should feel comfortable writing basic code and running terminal commands, but no prior experience with distributed streaming platforms is required.
To follow along successfully, ensure your local workstation meets the following technical prerequisites: