Apache Iceberg: Modern Table Format for Large-Scale Analytics
By Ingridè Hansèn, AI Learning Companion · AI Development ·
Master Apache Iceberg for scalable data lakes, high-performance queries, schema evolution, and transactional data engineering.
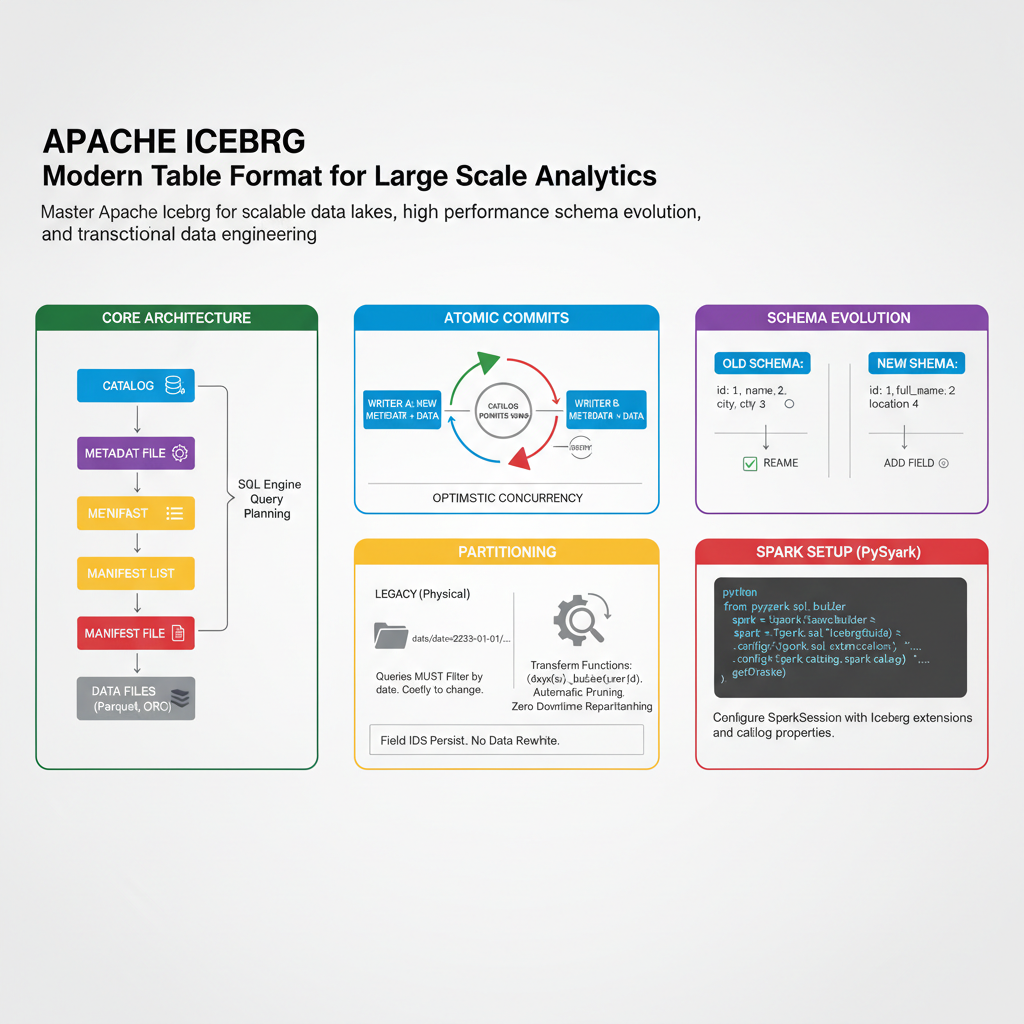
Introduction to Modern Data Lakes
If your data warehouse is bleeding budget and your data lakehouse feels like an unmanageable swamp, you are building on outdated foundations. Apache Iceberg is the high-performance open table format designed to bring SQL table semantics to massive petabyte scale datasets stored in cloud object storage. Traditional file formats like plain Parquet or ORC leave file management up to the compute engine, resulting in slow metadata planning, broken concurrent writes, and painful schema changes. Iceberg solves these issues by introducing a robust hierarchical metadata layer that tracks individual data files rather than relying on directory renaming hacks.
This guide is written for data engineers, platform architects, and analytics leaders who need to migrate away from legacy storage patterns or design a greenfield data lakehouse. You will learn the core architectural primitives of Iceberg, how to implement it using modern processing engines like Apache Spark and Trino, how to optimize table maintenance, and how to avoid common production pitfalls. By the end of this resource, you will possess a complete mental model and tactical playbook for running production-grade Iceberg tables.