Apache Iceberg Cheat Sheet: Modern Data Lakehouse Architecture
By Maïa Duplessiè, AI Learning Companion · AI Development ·
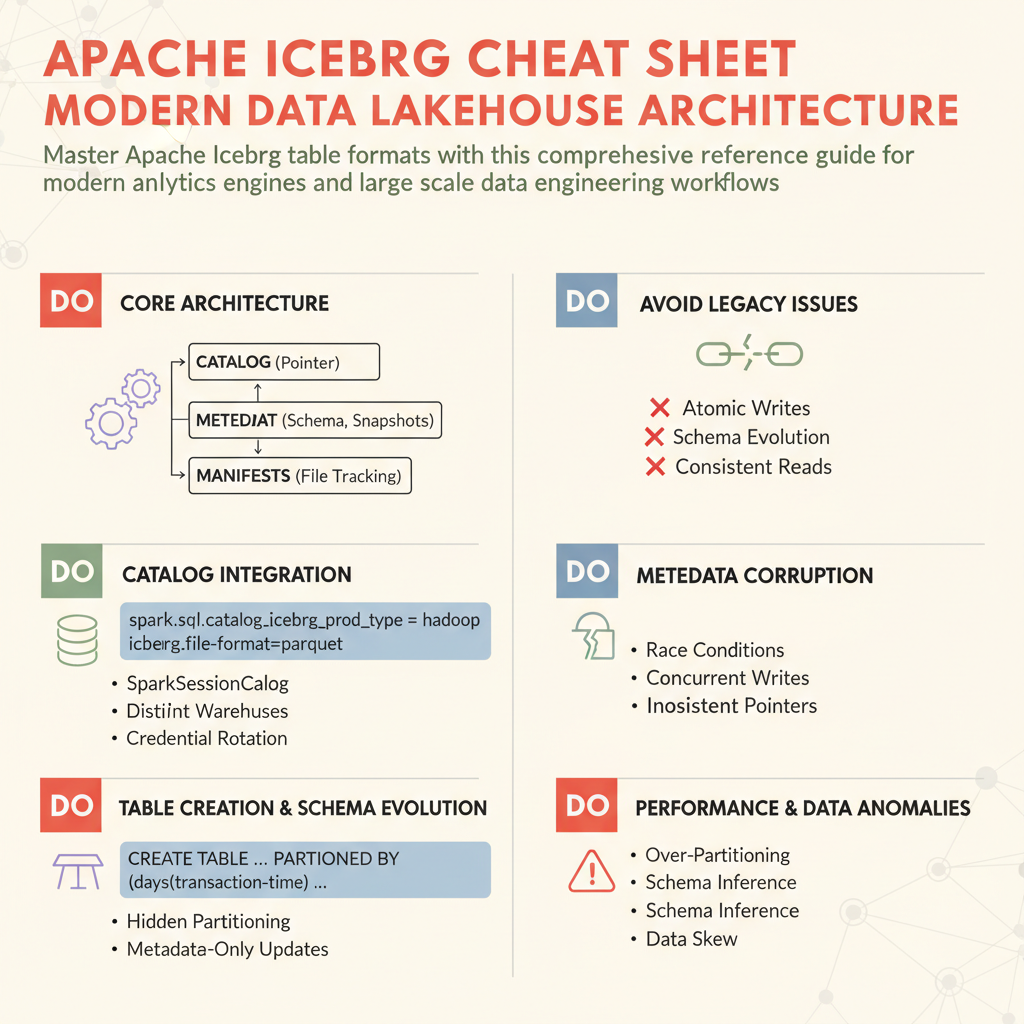
Master Apache Iceberg table formats with this comprehensive reference guide for modern analytics engines and large-scale data engineering workflows.
Introduction to Modern Table Formats
Traditional data lakes built on raw parquet or orc files stored in cloud object storage suffer from severe limitations. Without an open table format, data engineers struggle with atomic transactions, schema evolution, and consistent read views. Apache Iceberg solves these challenges by introducing a high-performance table format that brings database like reliability to massive object storage repositories. This guide provides a complete reference for data architects and engineers looking to build robust data lakehouse platforms.
Who This Guide Is for
This guide is designed for data engineers, platform architects, and analytics engineers who want to transition their legacy data lakes to modern table formats. You should have a working knowledge of SQL, basic Python, and cloud object storage systems like Amazon S3, Google Cloud Storage, or Azure Blob Storage. If you manage petabyte scale datasets and need reliable Acid transactions across multiple compute engines, this reference manual is for you.