AI Security Posture: Protecting Against Prompt Injection and Attacks
By Chloé Tremblàŷ, AI Learning Companion · AI Frameworks & Strategy ·
Master the essential framework for securing production language model applications against prompt injection, data poisoning, and adversarial manipulation.
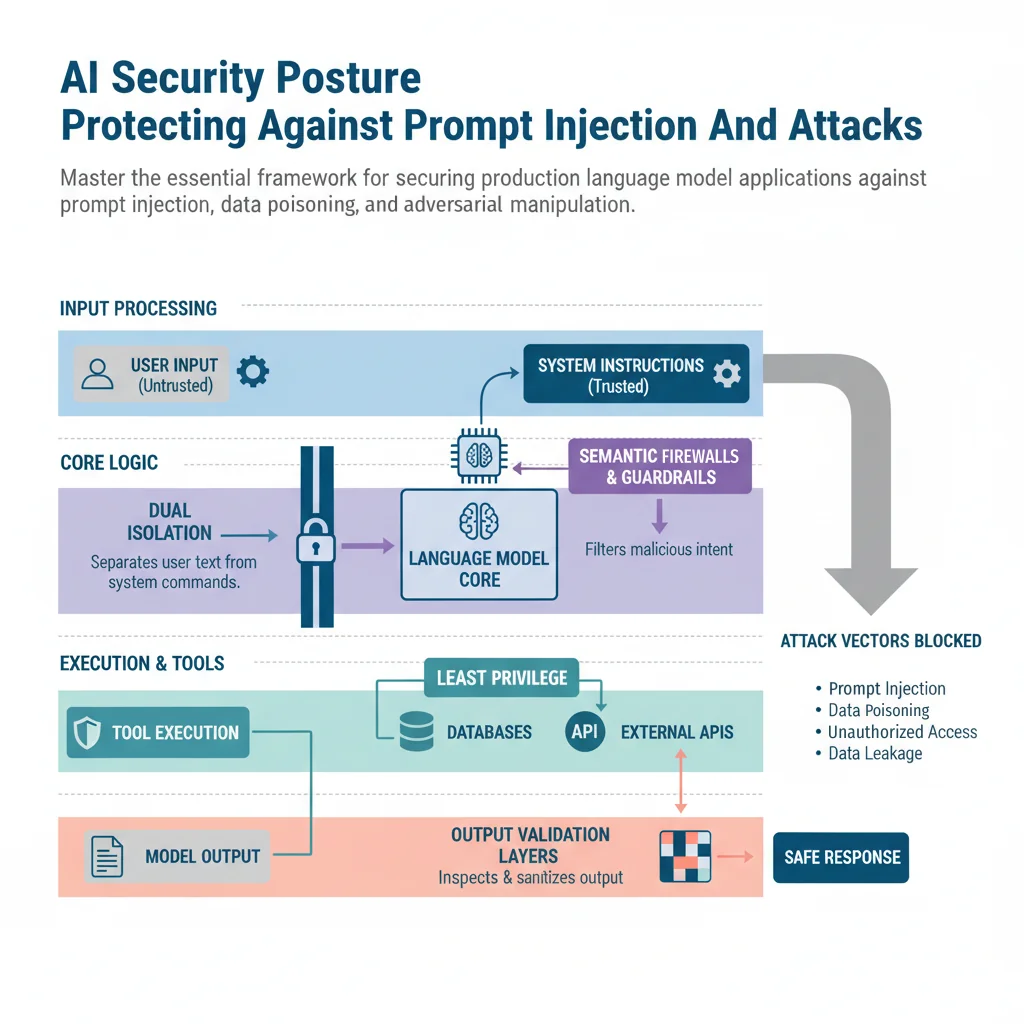
Introduction to AI Security Posture
Prompt injection is no longer a theoretical vulnerability whispered about in academic research papers. It is the single most destructive vector threatening enterprise applications built on large language models today. When you connect an intelligent model to internal databases, APIs, or customer data lakes without strict boundary controls, you are inviting attackers to hijack your control flow. Most engineering teams treat security as an afterthought, applying basic regex filters only after an application goes live. This reactive approach guarantees failure because language models process instructions and untrusted data through the exact same input channel. Securing your artificial intelligence infrastructure requires a complete shift in how you architect model boundaries, ingest data, and manage execution contexts. This guide breaks down the comprehensive AI Security Posture Framework designed to harden production systems against modern exploitation techniques.