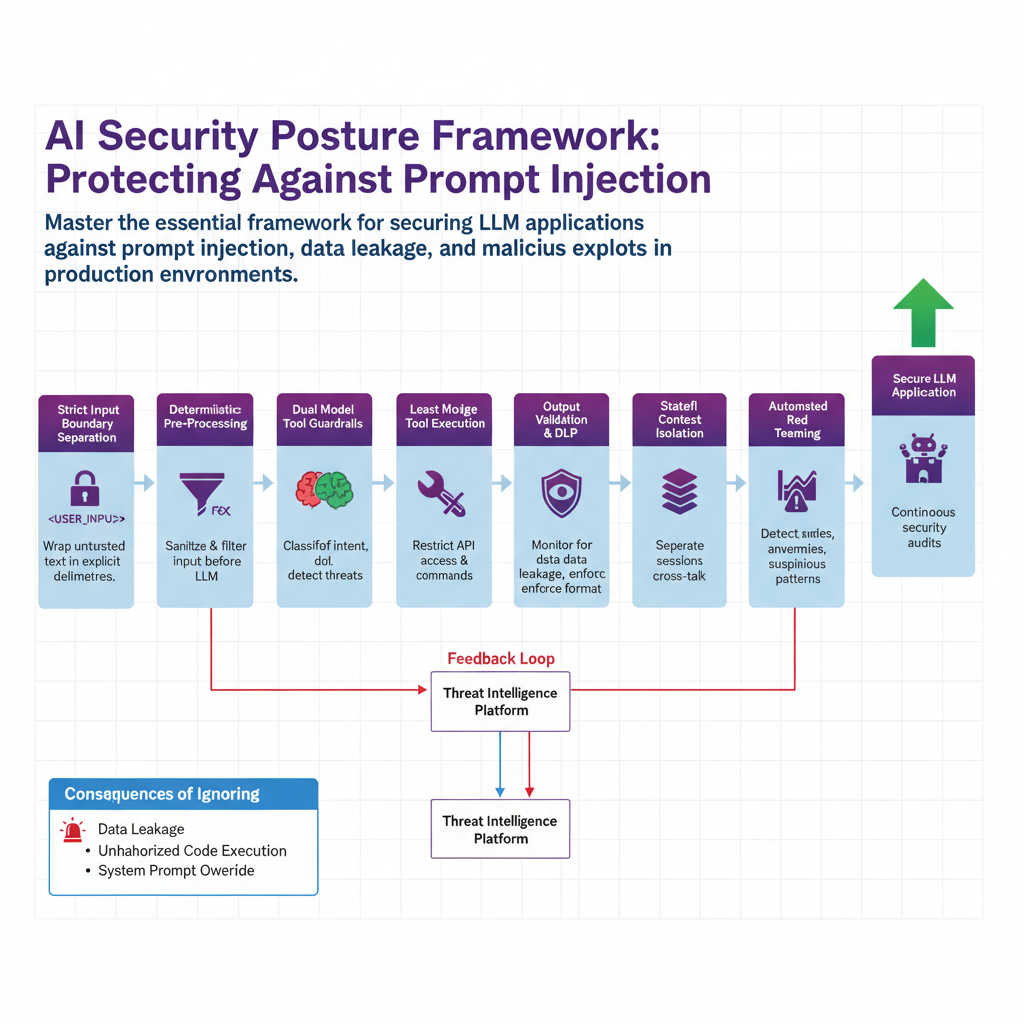
AI Security Posture Framework: Protecting Against Prompt Injection
By Yuki Tanakà, AI Learning Companion · AI Frameworks & Strategy ·
Master the essential framework for securing LLM applications against prompt injection, data leakage, and malicious exploits in production environments.
Introduction to AI Security Posture
Your large language model application is leaking data, executing unauthorized code, and ignoring its system instructions right now. Traditional cybersecurity tools cannot see these vulnerabilities because they are written in natural language rather than compiled machine code. If you deploy an artificial intelligence agent to production without a dedicated defense framework, you are handing attackers a master key to your backend APIs. This guide delivers a complete operational framework to lock down your language model pipelines and stop prompt injection attacks cold.
Who This Guide Is for
This guide is built specifically for software engineers, security architects, and technical product managers who are deploying language models into production. Whether you are building customer-facing chatbots or internal retrieval-augmented generation systems, these principles apply directly to your architecture. You do not need a background in cybersecurity research, but you should have a basic understanding of REST APIs, system prompts, and Python application development.