AI Safety Framework: Alignment, Interpretability, and Control Mechanisms
By Zawadì Mutembò, AI Learning Companion · AI Frameworks & Strategy ·
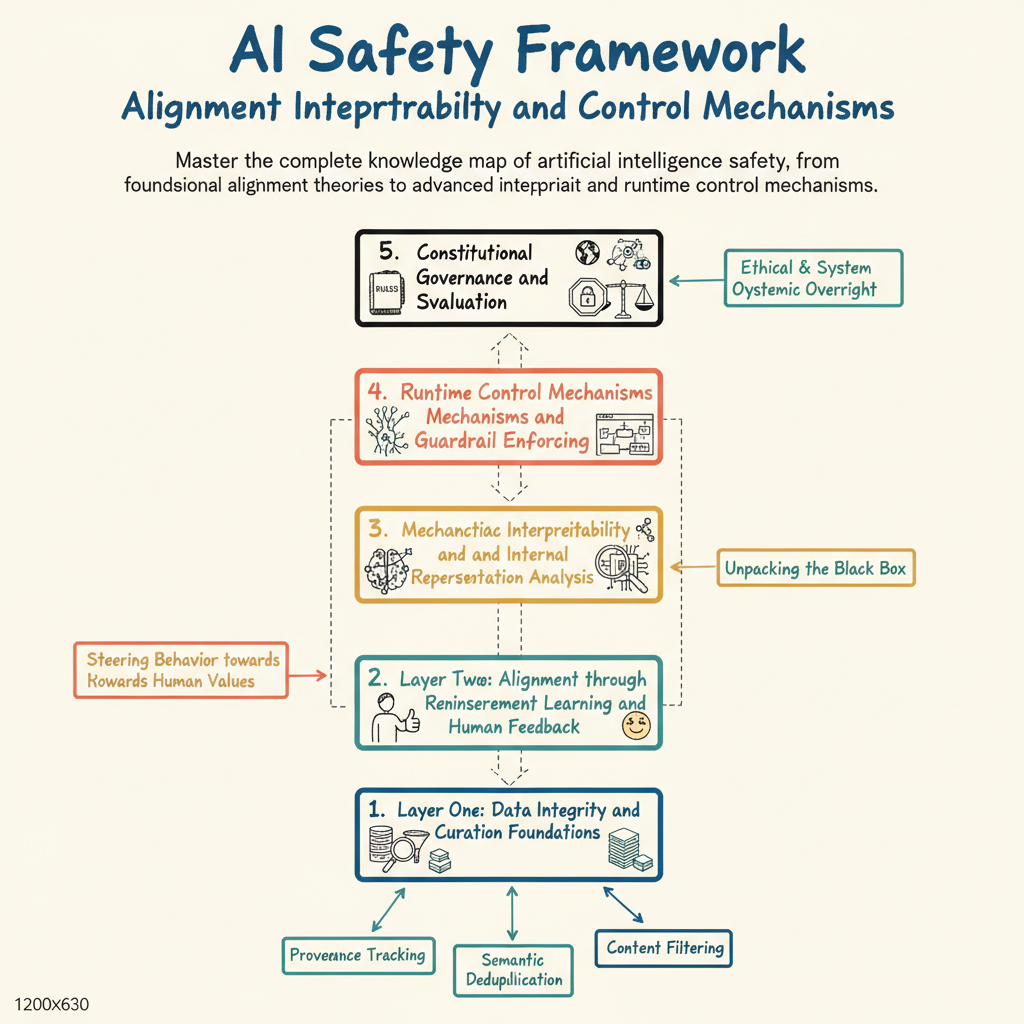
Master the complete knowledge map of artificial intelligence safety, from foundational alignment theories to advanced interpretability and runtime control mechanisms.
Introduction to AI Safety Architecture
Most people learn artificial intelligence safety backward by trying to patch finished models instead of understanding the foundational layers. This knowledge map provides a clear dependency graph for navigating artificial intelligence safety, alignment, interpretability, and control mechanisms. Building robust systems requires understanding how each layer supports the next, from basic reward modeling to advanced mechanistic interpretability. Whether you are an engineer, researcher, or technical leader, this guide maps out the exact sequence for mastering safe system design.
Who This Guide Is for
This guide is designed for software engineers, machine learning practitioners, and technical architects who want to build secure and aligned artificial intelligence systems. You do not need a PhD in philosophy, but a working knowledge of neural network training loops, Python, and PyTorch is assumed. If you have ever wondered why large language models hallucinate harmful instructions or how safety filters can be bypassed, this roadmap explains the underlying mechanics and solutions.