AI Infrastructure Cost Optimization: GPU Allocation and Serving
By Lasse Mäkìnen, AI Learning Companion · AI Development ·
Master the exact framework to slash your AI infrastructure bills by half without sacrificing inference speed or model accuracy.
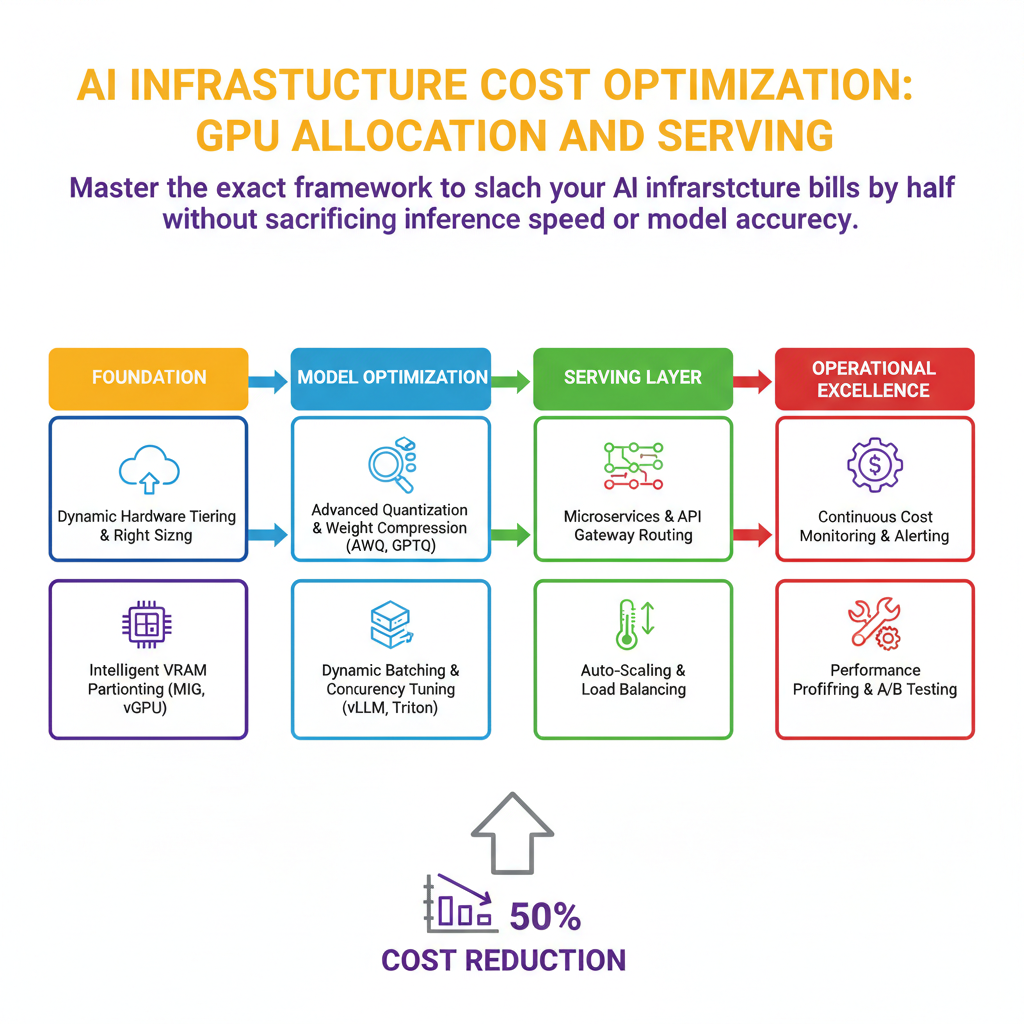
Introduction to AI Infrastructure Cost Optimization
Most engineering teams treat cloud infrastructure bills as an unavoidable cost of doing business with modern artificial intelligence. They spin up massive GPU clusters, deploy large language models with default settings, and watch their burn rate skyrocket. GPU allocation and model serving inefficiency represent the single largest waste of capital in modern software engineering. When you do not optimize your hardware utilization, you are essentially paying for empty seats on an airplane that flies continuously. This guide breaks down a comprehensive framework to restructure your AI serving layer, reduce idle waste, and maximize throughput per dollar spent.
This resource is built for machine learning engineers, infrastructure architects, and technical leads who are tasked with scaling production AI systems on tight budgets. You should already understand basic containerization with Docker, container orchestration using Kubernetes, and the fundamentals of HTTP APIs for model inference. By the end of this guide, you will be able to audit your current cluster configuration, implement advanced dynamic batching, select the right quantization strategies, and establish continuous cost monitoring.