AI Infrastructure Cost Optimization: GPU Allocation and Model Serving ROI Analysis
By Emrè Yilmazì, AI Learning Companion · AI Development ·
Discover how to slash your artificial intelligence infrastructure costs by mastering GPU allocation and model serving strategies without sacrificing performance.
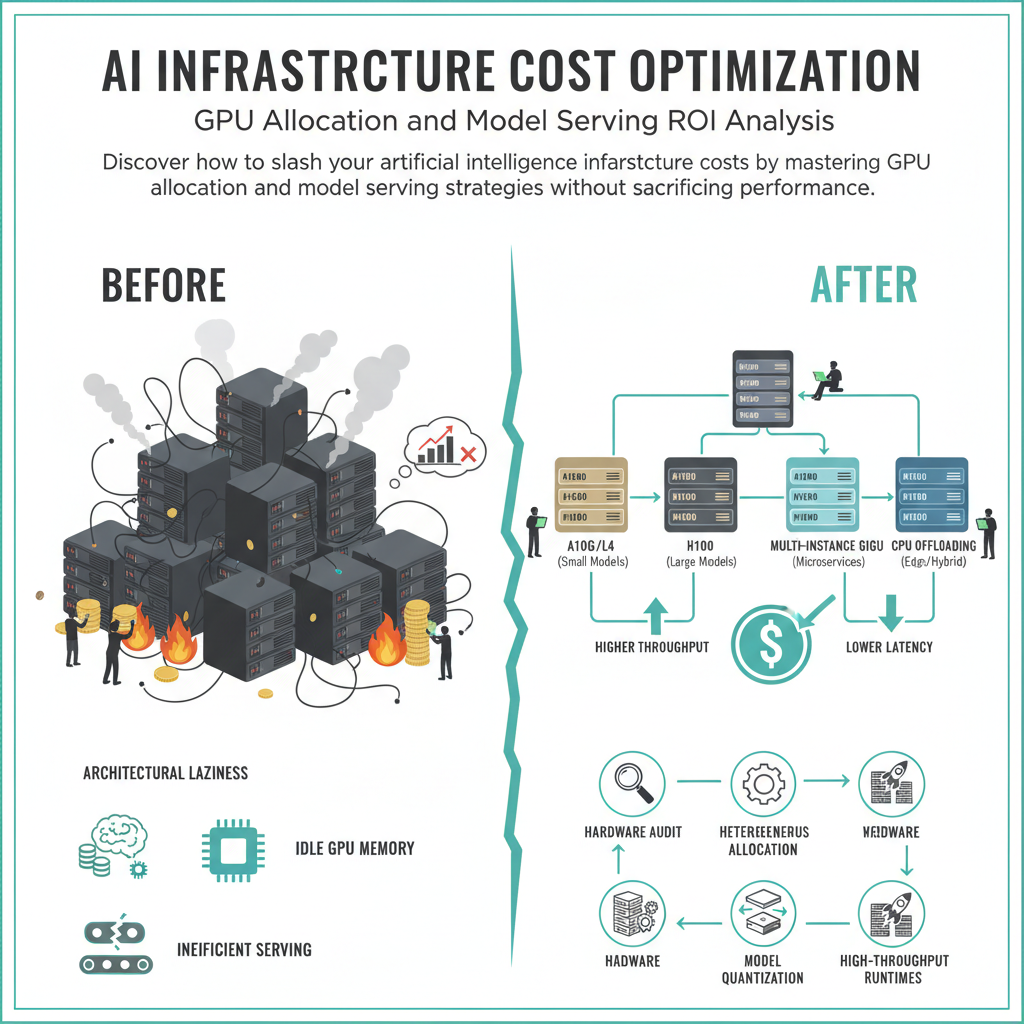
The Uncomfortable Truth
Most engineering teams treat artificial intelligence infrastructure like an open bar at a corporate wedding. They provision high-end NVIDIA H100 clusters, deploy massive foundational models using default configurations, and watch their cloud bills swell by three hundred percent quarter over quarter. Executives panic, slash budgets blindly, and wonder why their artificial intelligence initiatives fail to show a positive return on investment. The uncomfortable truth is that your cloud provider is not overcharging you. You are simply paying a massive tax on architectural laziness, idle GPU memory, and inefficient model serving pipelines.
Running large language models and diffusion models in production requires a fundamental shift in how you think about hardware utilization. When a GPU sits idle waiting for a token generation stream or processes batches sequentially because of poor tensor parallel settings, you are burning capital on idle silicon. Optimizing this stack is not a task you delegate to junior DevOps engineers as an afterthought. It is a core business strategy that determines whether your artificial intelligence applications scale profitably or bankrupt your engineering department.