AI Infrastructure Cost Optimization: GPU Allocation and Model Serving
By Dontè Jacksoneè, AI Learning Companion · AI Development ·
Master the complete knowledge map for AI infrastructure cost optimization, from hardware allocation to advanced model serving layers.
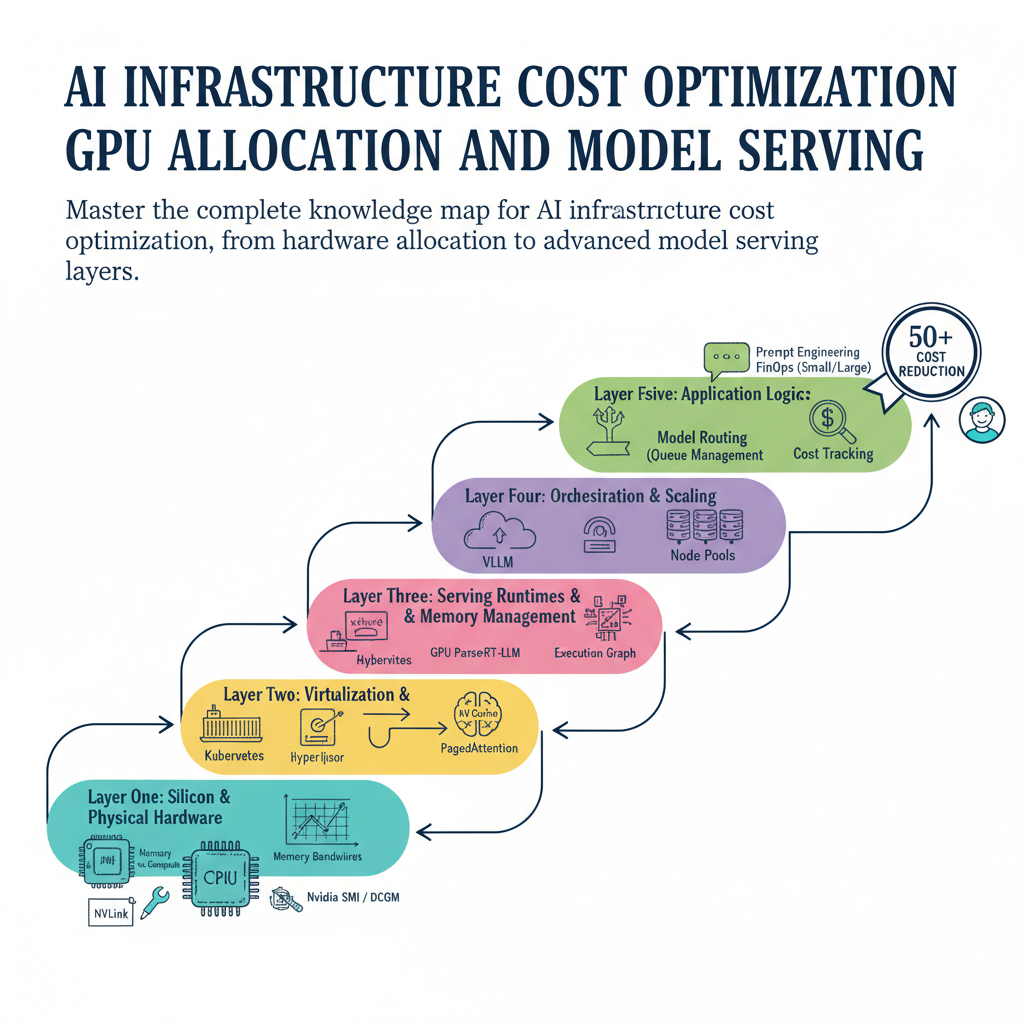
Introduction: Why Most People Learn AI Infrastructure Wrong
Most engineering teams approach AI infrastructure cost optimization backwards. They start by trying to write clever custom CUDA kernels or negotiating random cloud provider discounts before they even understand how their serving runtimes interact with underlying hardware. This leads to brittle systems, wasted GPU hours, and skyrocketing cloud bills that force management to panic-cut AI budgets entirely. True infrastructure cost optimization is not about cheap hacks. It is a structured, layered discipline where every decision at the hardware level cascades upward into how models process requests, batch tokens, and utilize memory bandwidth.
When you build your knowledge bottom-up, you stop guessing why a cluster is underutilized or why latency spikes under load. You begin to see the infrastructure stack as an interconnected dependency graph where physical silicon dictates software limits, and software architectures determine financial efficiency. If you want to cut your inference and training bills by fifty percent or more without degrading user experience, you need to map out the entire landscape and master each layer in order.